
📝 Guestbook
Messages and mentions from across the web. You can mention this site via Webmention. You can also mention @blog@platypush.tech on the Fediverse.
Reactions
How to interact with this page
Webmentions
To interact via Webmentions, send an activity that references this URL from a platform that supports Webmentions, such as Lemmy, WordPress with Webmention plugins, or any IndieWeb-compatible site.
ActivityPub
- Follow @blog@platypush.tech on your ActivityPub platform (e.g. Mastodon, Misskey, Pleroma, Lemmy).
- Mention @blog@platypush.tech in a post to feature on the Guestbook.
Reasons for yet another ActivityPub server
The beginning — Mastodon
I've been running Mastodon-compatible services for a while, starting with my first now defunct Mastodon instance at social.platypush.tech.
Mastodon is a great gateway drug for the Fediverse, but it soon started to feel tight for me.
Features often land in Mastodon only when other federated platforms have already embraced them for a while (e.g. post edits), and they often land in ways that are incompatible with what other platforms have already implemented (e.g. quotes).
And many other features that I wanted for a rich social media experience (emoji reactions, Markdown support, configurable number of profile fields, configurable maximum number of characters, configurable number of media attachments, Webmentions, backfilling of statuses and other activities from remote instances, code blocks, inline images, custom frontends, LaTeX formulas, a simpler and more complete process for account migrations...) just never landed at all.
I ended up, like many others, maintaining my own fork of Mastodon, with all the patches for features I wanted and that would have probably never been merged upstream.
At some point I realized that keeping my own fork up-to-date with all the upstream changes wasn't worth the effort, and I started to look for a better way to run Mastodon-compatible services.
Another factor that influenced my decision was Mastodon's unjustifiably high resource footprint.
My old instance used to run on a dedicated VPS with 8 GB of RAM and 500 GB of disk space.
It only had me and another active user on it.
And yet all the federated load, with all of its eager operations managed by a bloated Ruby-on-Rails + Sidekiq stack, was sufficient to choke everything, even if I regularly ran cleanups.
Down the rabbit whole — Akkoma
At some point I started looking around for federated alternatives compatible with Mastodon that had a much lower resource footprint and provided most of the features I wanted.
I soon discovered Akkoma, and I've used it for a few years as my main driver - the last instance was manganiello.eu.
Akkoma filled many of Mastodon's gaps that mattered to me:
- Markdown posts
- Configurable number of post characters
- Configurable number of profile fields
- Code blocks (no syntax highlighting though)
- Emoji reactions
- Custom frontends (but not customizable on a user level)
It still left some gaps, especially some compatibility gaps with Mastodon (indexable flag on accounts, support for Mastodon quotes, remote profile badge verification...), but for a long while I was satisfied with what it provided.
Until recently I was also the maintainer of the AUR akkoma package (now looking for a new maintainer).
But after a while I also started to feel uncomfortable with Akkoma's limitations.
Mastodon-compatible quotes were a dealbreaker, and my implementation failed to get approved upstream - ending up on the fork I ran on my instance.
Other features, like full bidirectional verification for profile badges and support for the indexable flag, also ended up living only on my fork.
Other issues, like proper compatibility with Audio activities from e.g. Funkwhale or Songhive, also made the experience less pleasant.
Akkoma however proved to show much more clemency towards my hardware resources than Mastodon did.
But the price to pay was to implement the features I wanted in a language (Elixir) that was quite exotic and unfamiliar to me (even though I ended up learning a lot from it).
I also couldn't find much documentation about e.g. Akkoma jobs or configuration.
I found Akkoma's documentation to be quite minimal in terms of content.
Understanding some configuration options or what job to run for a particular task often required me to look at the code itself.
Another issue with Akkoma was with the frontend.
I know that the default pleroma-fe can be quite polarizing, and that people either love it or hate it.
I belonged to the category of those who, no matter what, never managed to like it.
Luckily Akkoma could be configured to use alternative frontends, and I ended up liking the style of Soapbox, and even more that of its fork Mangane.
But I still felt that those frontends weren't particularly rich in terms of features, nor particularly curated around the edges.
Plus, the admin panel was an afterthough provided as a separate frontend rather than a first-class citizen like in Mastodon, and the UX was also poorly curated.
Still, the Soapbox/Mangane style ended up heavily inspiring the design of the default Yonder frontend.
Building Yonder
I started building Yonder (source code, Github mirror) a while ago, as a minimal PoC for an ActivityPub server in Rust .
It's been on a back burner on my hard drive for a while, but now I feel that it's mature enough to be my main driver on the Fediverse.
Yonder is a self-hosted, Mastodon-compatible ActivityPub server. The entire service — HTTP API, federation, streaming, media, moderation, admin panel, background jobs — is one binary. The only services it needs are PostgreSQL and Redis.
It speaks the Mastodon client API (v1 and v2), so Tusky, Ivory, Elk, Phanpy, Mona and every other Mastodon app just works when pointed at your instance.
It also implements a good subset of the Pleroma/Akkoma API dialects, which means that clients like Moshidon and other Pleroma-compatible apps can also access those features (e.g. Markdown content type for posts and custom emojis).
It speaks ActivityPub, so your users federate with Mastodon, Akkoma, Pleroma, Misskey and the rest of the Fediverse.
Name and meaning
Yonder (adv. or adj., /ˈjaʊndə/) is an Old English term for "over there". Something distant but usually within sight.
I chose it as the name for this project because it relays, together with the logo (a large circle connected to three other circles), the idea of connecting things distant but within reach.
What you get
Posting & timelines
- Rich posts in plain text or Markdown, with content warnings, polls, media attachments with editable alt text, scheduled posts, editing and saved drafts.
- Quote posts with author authorization (FEP-044f-style, with fallback to FEP-e232 Pleroma/Akkoma/Misskey compatible quotes), custom emoji reactions, replies, boosts and likes.
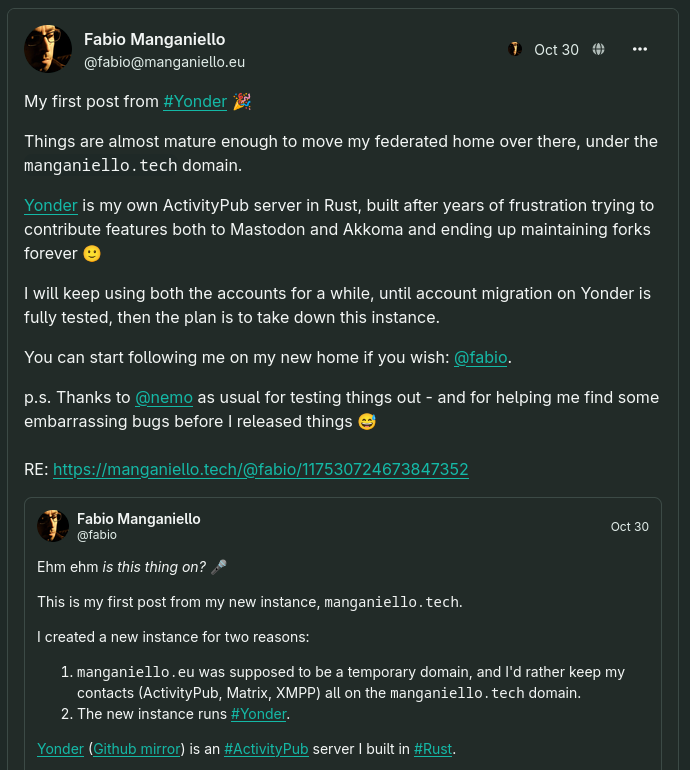
- Every timeline Mastodon has: home, local, federated, hashtag timelines, user-defined lists — with real-time updates over the standard Mastodon streaming WebSocket.
- Hashtags you can follow into your home feed and server-side filters (
warn/hide/blur) that apply across every timeline.
Social & federated
- Full ActivityPub federation via Pubby, with durable at-least-once delivery. I built Pubby as a general-purpose ActivityPub library that takes care of the all the plumbing behind the scenes, initially with Python bindings to power Madblog and Songhive, and it gained Rust bindings with features parity with the Python SDK in order to power Yonder - available as
pubby-sdkcrate. - Notifications in-app over WebSocket, Web Push (VAPID) and email, with per-type preferences.
- A progressive Web app (PWA) optimized for mobile and with support for native notifications.
- The bundled Web UI ships in five languages including full RTL support, with light and dark themes and custom accent colors.
- Custom emojis — per-instance emoji and emoji packs.
- Custom number of characters, custom number of profile fields, custom number of media attachments and custom number of pinned posts.
- RSS and Atom feeds for profiles, tags and lists; oEmbed/embeddable status cards.
Moderation & administration
- User-side: mutes, blocks, reports (optionally forwarded to the remote instance via
Flag), server-side content filters. - Instance-side: user limiting and suspension, domain blocks, federation relays, and a comprehensive admin panel delivered as a first-class citizen.
- Every registration policy:
open,invite-only,approval-requiredorclosed.
Platform
- One single Rust binary — stack:
axum,sqlx,tokio. - OAuth2 provider with authorization-code + PKCE, device flow, and scoped revocable API tokens.
- Pluggable frontends: the bundled Vue 3 SPA is just the default; alternative frontends can be installed alongside it. Users can pick their favourite frontend, preferences are stored in the browser session.
- OpenAPI 3 spec at
/openapi.jsonwith bundled Swagger UI. - Safety defaults: argon2id passwords, SSRF-guarded remote fetches, Redis-backed rate limits, TOTP two-factor.
What's new
Account migration
Account migration is a first-class feature: moving an account to or from another server, followers and all, is a supported flow, compatible with Mastodon and Akkoma.
On top of that, Yonder supports importing activities from the old account in two ways:
- Standard CSV import/export (compatible with Mastodon/Pleroma/Akkoma)
- OAuth2-authenticated API fetches.
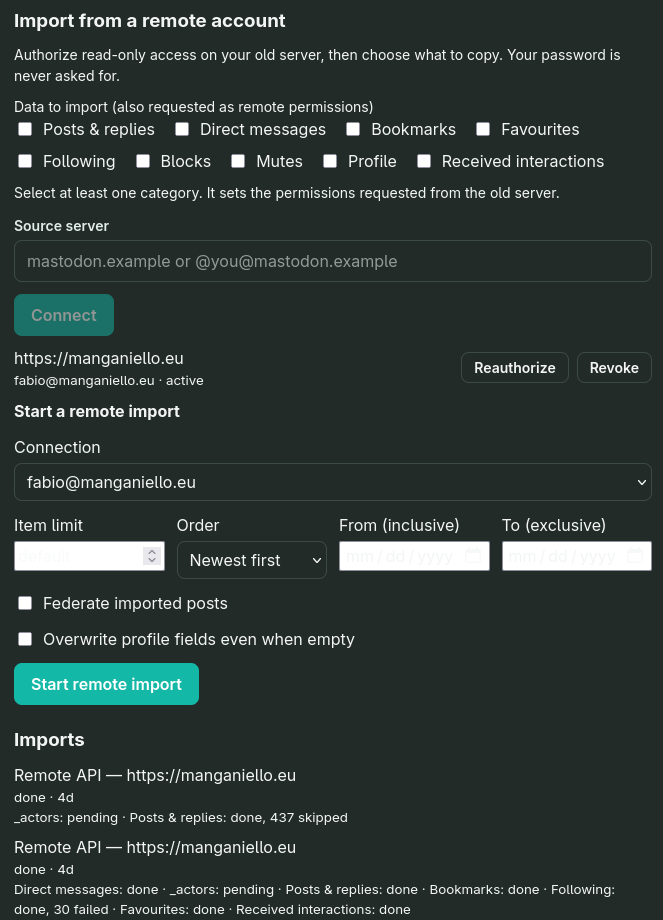
You login to your old account through Yonder's interface, you pick what you want to import from your old account (including private messages, likes, boosts, replies, etc.), click "Start remote import", and everything from your old account will be copied over - as a native activity that originated from the new account, with the original timestamps respected.
The user can also decide whether the imported activities will fan out to federated instances or only be stored on the local database - prevents avoidable federation noise over imports, the activities can be selectively federated by simply boosting them or editing an old post.
The only thing that Yonder doesn't support is importing received likes, boosts and replies - for the simple reason that it doesn't want to forge federated activities or rewire threads in ways that don't reflect what other instances see.
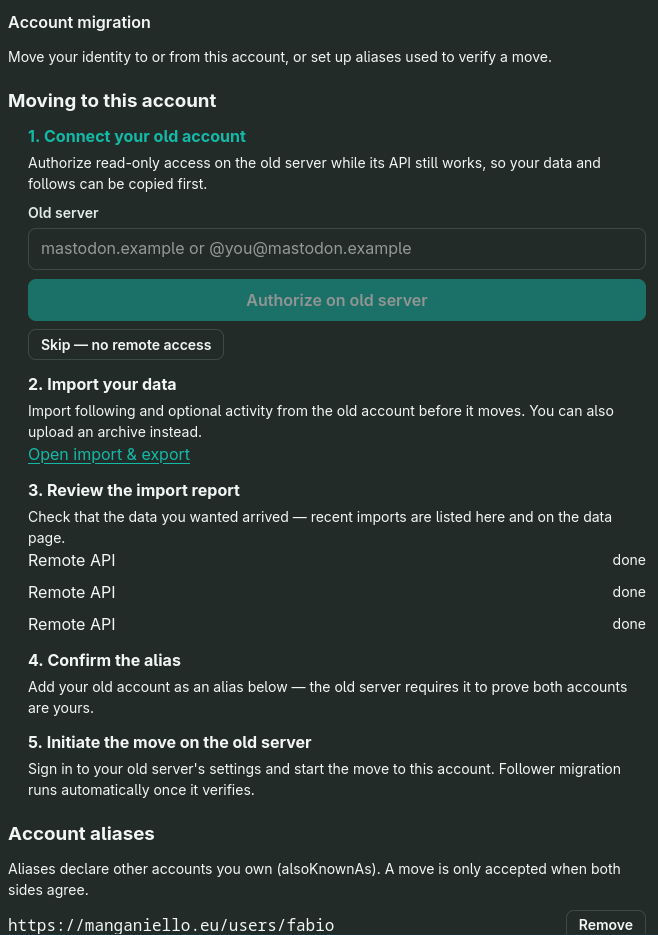
The UX of the account migration flow has also been re-thought as a step-by-step process (connecting the old account over OAuth2, importing the data over API crawlers or CSV backups, reviewing the import process, creating an alias and moving followers), making the process much more intuitive and mistakes harder.
See the full federated picture all the time
One of the most confusing (and often infuriating) things about the Fediverse is that what you see on your local instance is often a very small subset of what's actually available on the Fediverse (unless you are on a large instance like mastodon.social, and even in that case many activities from the fringes of the Fediverse are lost).
Your instance only receives what its peers send to it. And an instance's peers depend on who your users follow, which relays you wired your instance to, and who your users interact with.
This has an unintended consequence: that content that never reaches your instance is invisible to you. Unless you trigger an explicit fetch, e.g. through a search query or some import job. And even then, you probably won't see a lot of likes, boosts and replies a remote activity has received, nor the real number of followers of a user.
Yonder solves this problem by adding a couple of new endpoints to the standard Mastodon API, and slightly modifying how some of the existing endpoints behave in order to maintain back-compatibility with existing apps.
/api/v1/accounts/{id}/sync_remote. This allows users to explicitly sync the latest<n>activities from the account{id}from the remote instance to the local database. If your Mastodon instance sees an account for the first time, and no local users follow that account, their timeline will probably appear empty, and they will show as having zero followers/followed accounts. Yonder fixes this visibility gap by adding a "Sync with<remote-instance>" button next to remote profiles, which triggers a remote fetch for their next<n>activities.- Followers and followed accounts are also synchronized with the remote instance, so you see the actual numbers. Upon calls to the
/followersendpoint, the list is lazily fetched and you can navigate it from your local instance - without having to open the original profile URL to see the actual numbers. /api/v1/statuses/{id}/fetch_remote_context. This endpoint is called by the Yonder frontend whenever you expand a post that belongs to a remote thread. What it does is to fetch behind the scenes all the statuses that belong to the same parent line, with a default maximum depth of 20. This, in my opinion, matches the expected behavior from a social app user. If I see a comment from a friend on another thread and I click on it, the most relevant thing I want to see is the direct path of statuses from the root of the thread down to the status I clicked on, plus the next 2-3 direct children. The client ends up seeing exactly the same context as the instance of the post's author. This is back-compatible also with existing Mastodon apps - calls to the/contextendpoint will trigger/fetch_remote_contextbehind the scenes if needed, and a refresh of the status 2-3 seconds later should show all the expanded remote posts in that path. Siblings and descendants from other paths are not fetched by default, but they are fetched if the user expands statuses on those paths. This approach means that fetches of remote threads provide a much more complete picture than that provided by Mastodon by default (you get to see exactly the same view as the author of that post, not only the subset explicitly send to your instance), while simultaneously being more efficient than what e.g. Mastodon does (fetch overhead is capped by the depth of the path, set to 20 by default, instead of trying to eagerly fetch the whole tree with no boundaries).
Another handful of useful API extensions
POST/DELETE /api/v1/accounts/{id}/subscribe: subscribe/unsubscribe to an account's activities without publicly following them.GET /api/v1/trends/tags: browse global or local trending hashtags, with support for pagination and time ranges.POST /api/v1/admin/accounts/{id}/reset_password: programmatically send a user password reset link directly to their email.POST /api/v1/admin/statuses/{id}/action: apply granular moderation to individual statuses (delete, mark as sensitive, add content warning).
Trending hashtags
This is something that for some reason Mastodon removed at some point, but that I find very useful.
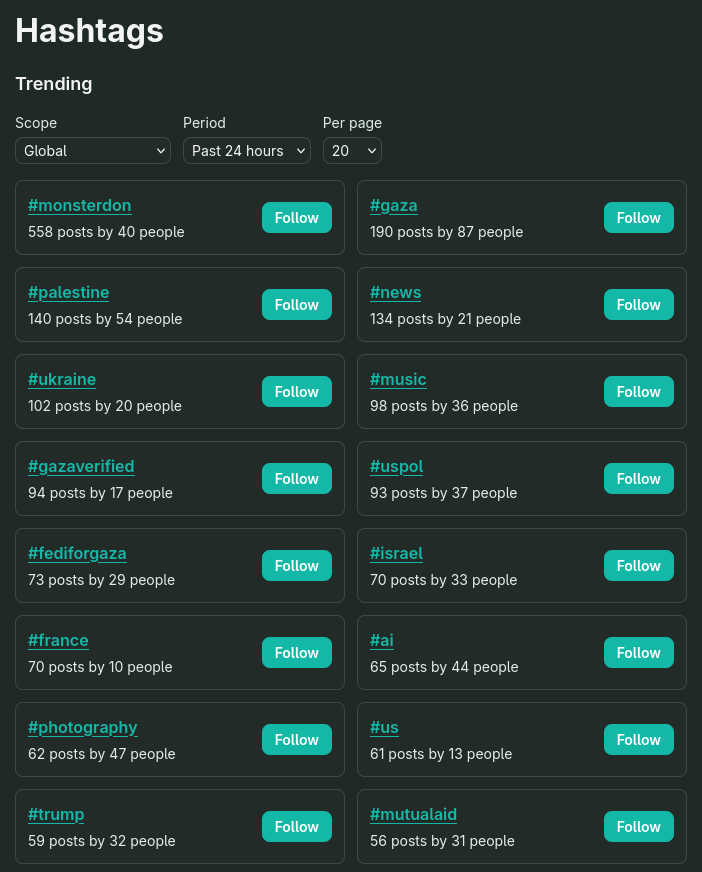
Yonder makes it easy not only to follow hashtags, but to have a view of all the hashtags that are trending over the local instance or over all the known Fediverse, over a given period of time, and with support for pagination.
Direct messages as real conversations
Direct messages in Yonder are real conversations, not just an ungrouped timeline of cards with a lock on them.
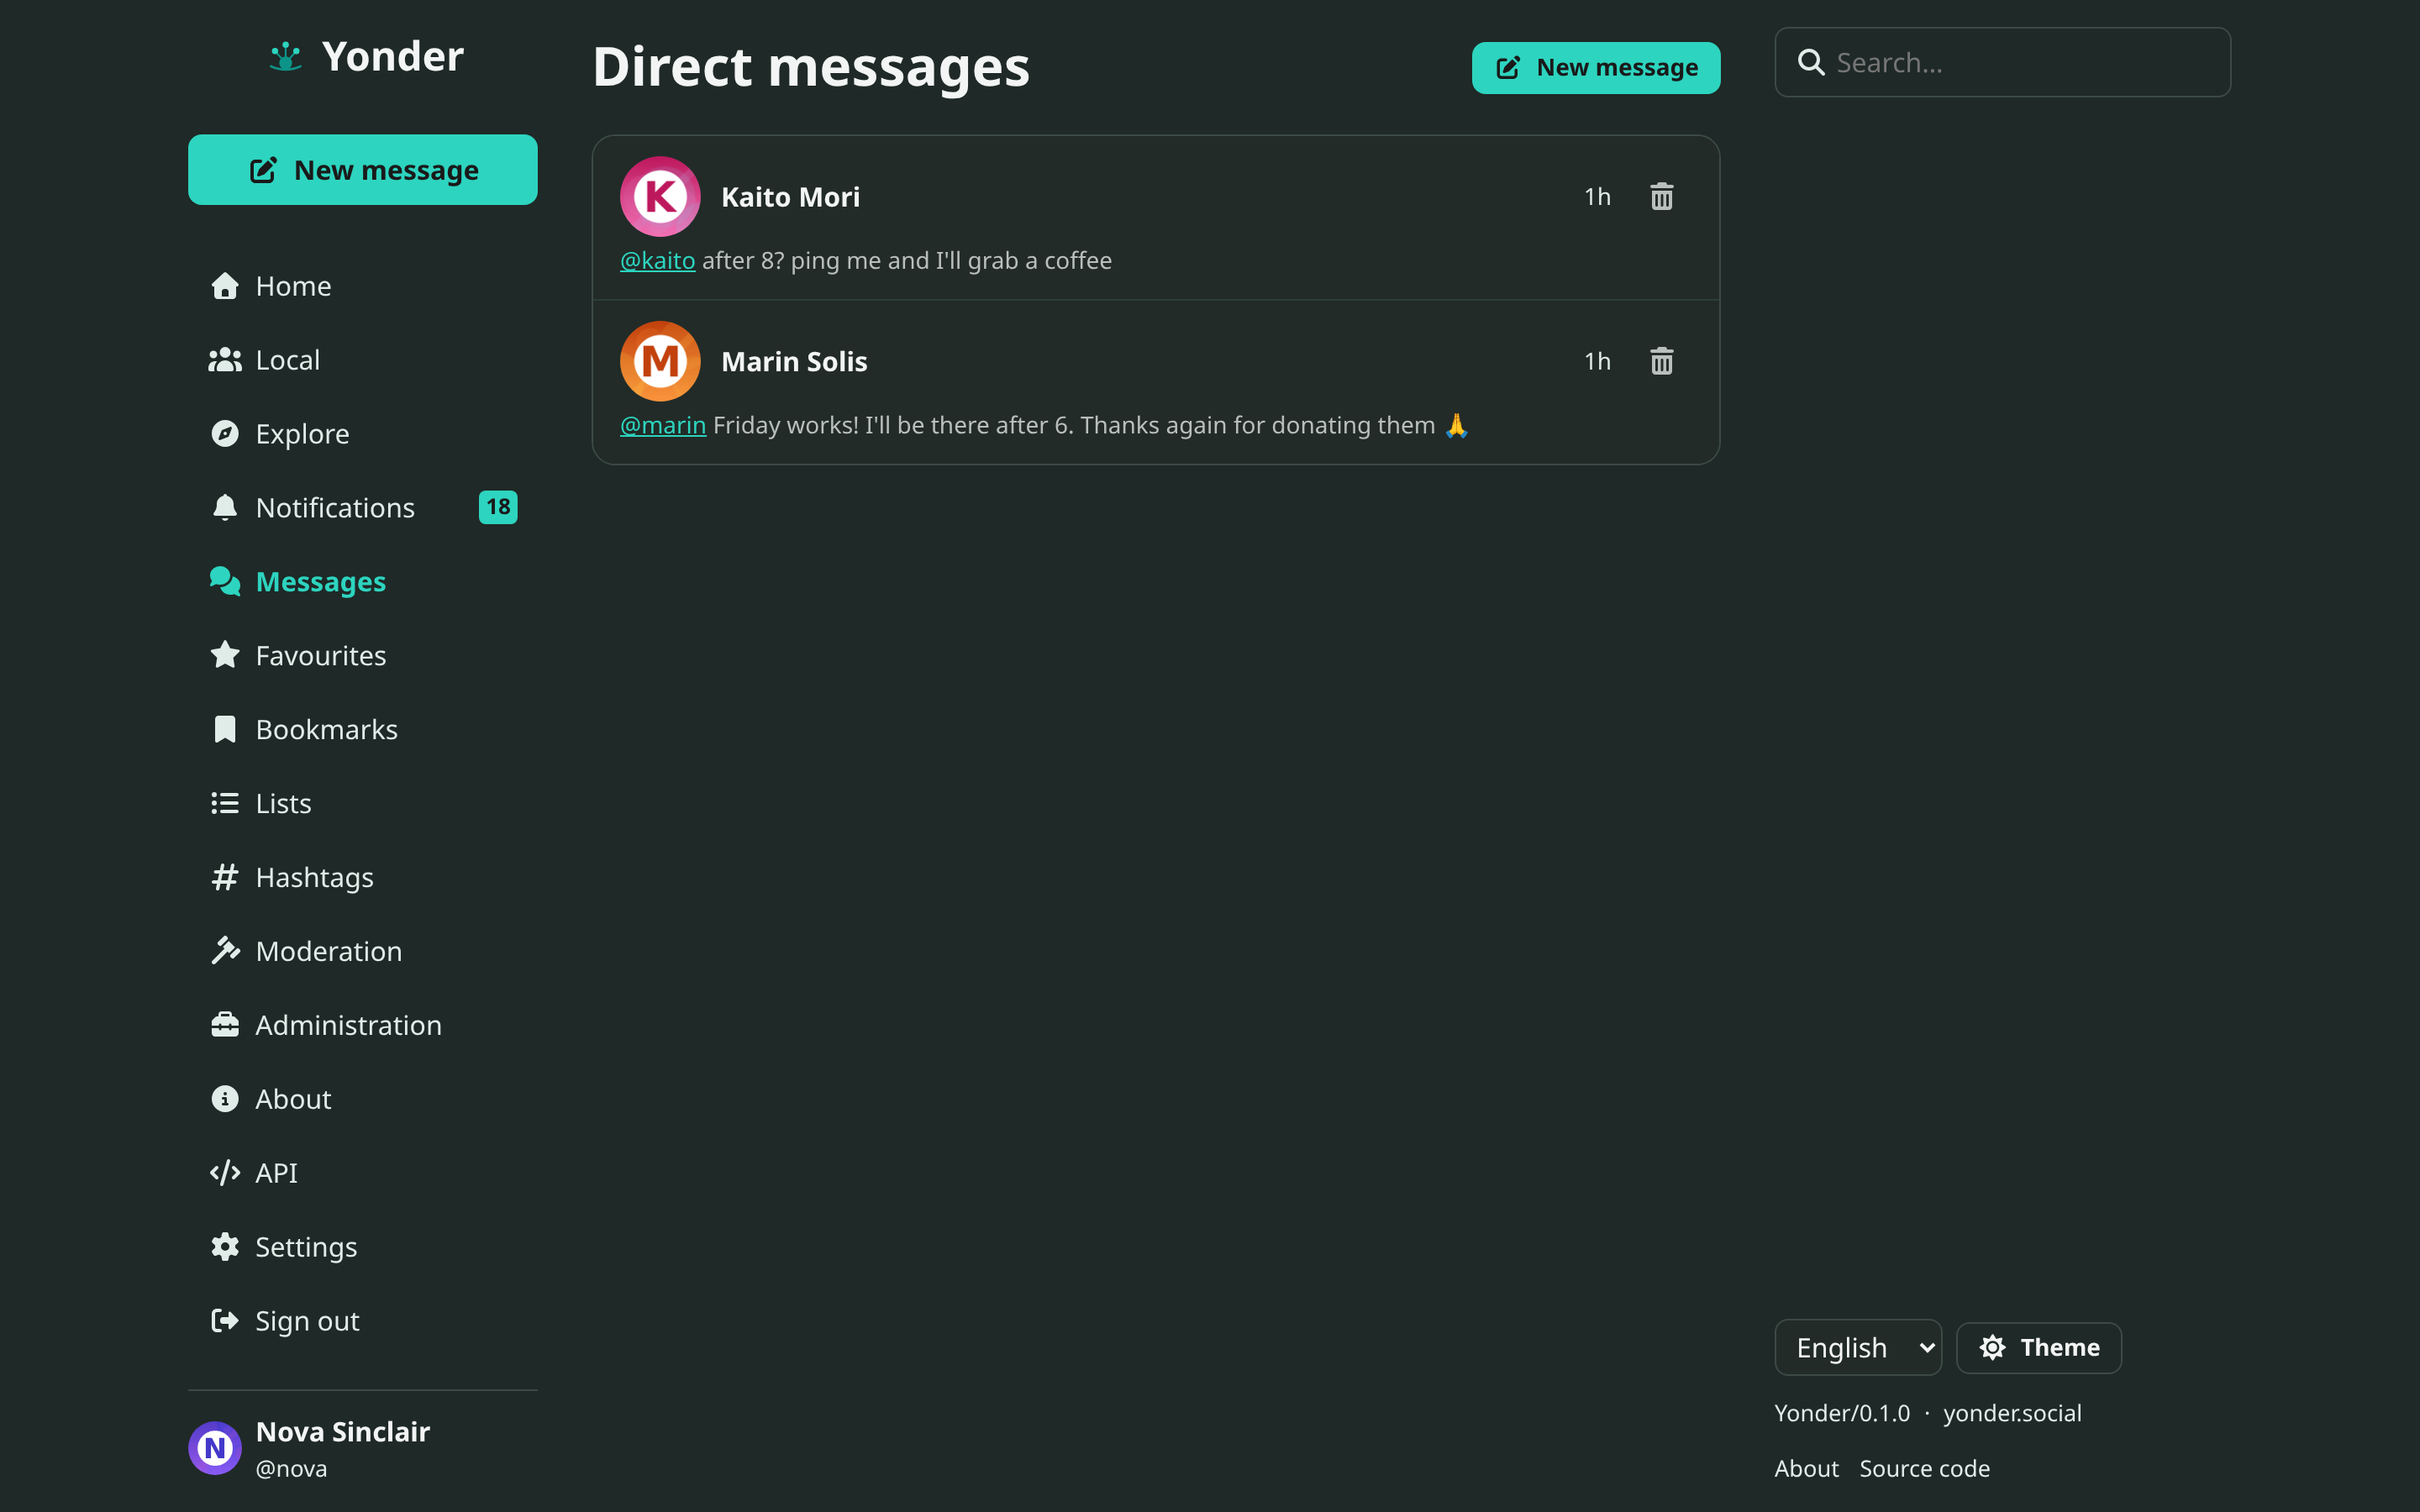
This is similar to what users expects by social networks like X, Facebook or Instagram - private messages are not a timeline, they are grouped conversations, and it should be easy to find a private message from a month ago even if you received hundreds of messages on a single unrelated conversation in the meantime.
Webmentions
Webmentions are first-class citizens supported in both directions.
What this means is that:
- If a blog or federated actor
example.blogthat supports Webmentions posts a link toexample.social/status/123,example.socialwill process the Webmention and render it as a normal reply or reaction. The Webmentions actor will also be transparently rendered as a virtual user on the platform. - If you link
example.blogin a post onexample.social, andexample.blogsupports Webmentions, then the target will receive a Webmention request, and your social activity may be natively rendered under the blog article.
Webmentions are powered by my webmentions library - which, just like Pubby, was initially built in Python to support Webmentions on Madblog and Songhive, and then ported to Rust with features parity with the Python SDK - available as webmentions-sdk crate.
LaTeX
Instances like mathstodon.xyz run their own forks of Mastodon with support for LaTeX formulas.
But they use MathJax, which means that formulas are only rendered on the frontend, and only if you see them from that instance.
Yonder goes one step further and it adds rendering of LaTeX formulas directly on the backend.
You can provide your rendering script, set math.enabled = true in your configuration, and set math.command to your LaTeX rendering command.
Any command that takes the LaTeX formula on the stdin and returns an image on stdout works.
The repository ships a latex-math-render.sh script that is already compatible with tectonic and pdflatex.
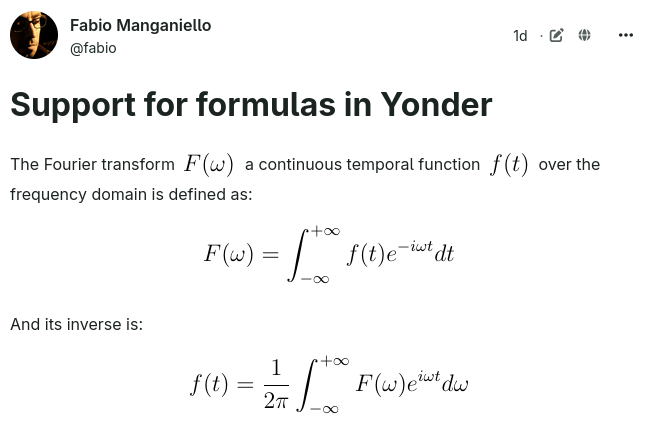
Being rendered on the backend, the formulas are also rendered on clients that don't support frontend rendering through MathJax.
If the server or the client support inline images (e.g. Phanpy), then formulas will be rendered inline.
If it supports math-type attachments, then the formulas will be rendered at the bottom of the post.
Otherwise, they will graciously fall back to image attachments, with LaTeX-style references ((1), (2)...) as links in the post.
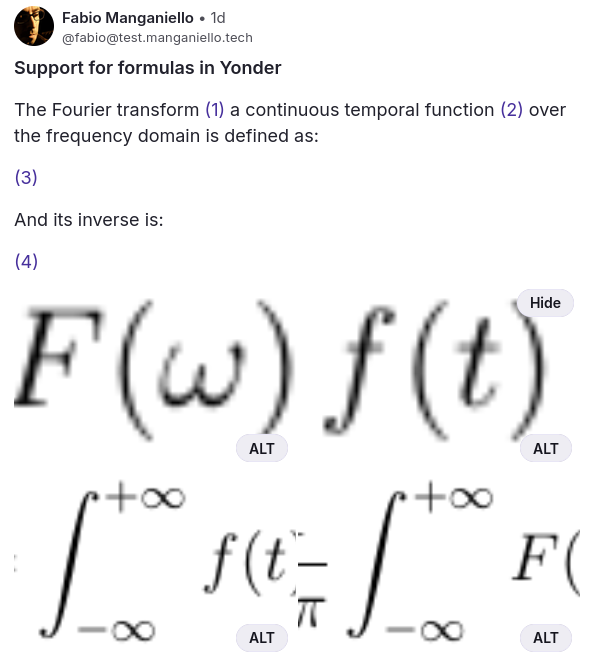
Inline images
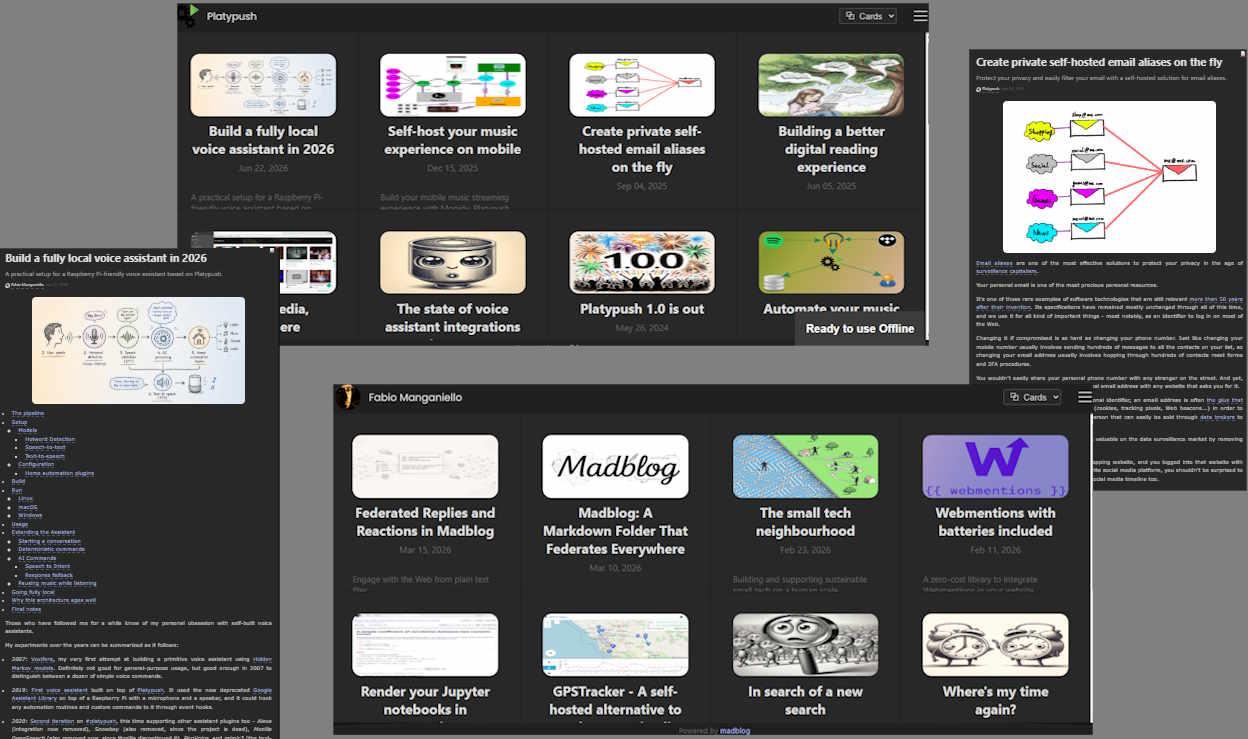
Yonder supports inline images via standard Markdown:

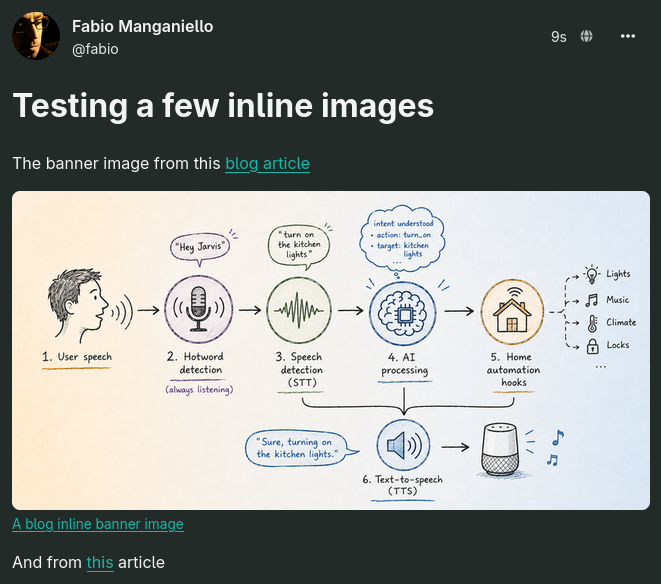
Embeddables
Embed your posts in blog, Websites and anywhere on the Web. Click on the context menu of a post, select "Embed", and copy the snippet:
<div class="yonder-embed" data-status="{status-id}">
  <a href="https://{instance}/statuses/{status-id}/embed">Post by @{user}@{instance}</a>
</div>
<script async src="https://{instance}/embed.js" charset="utf-8"></script>
<noscript>
  <iframe src="https://{instance}/statuses/{status-id}/embed" width="100%" height="400" frameborder="0" loading="lazy" title="Post by @{user}@{instance}" />
</noscript>
An example:
Reactions to the status are fetched from the instance, if the user updates their status the referring page will update as well. If the status is deleted, it will also be deleted from the referring page. And Webmentions towards the Yonder target will also be processed if supported by the referring page, so the referring page will also be shown under the thread as a federated reply.
How it compares
I want to be honest here rather than hype-y, because "yet another Mastodon-compatible server" deserves scrutiny.
A feature matrix would be the natural way to do this, but matrices are painful to read on a phone, so here's a plain-language summary of where each implementation actually stands (as of late 2026). All of them speak ActivityPub and the Mastodon client API (Yonder implements both the v1 and v2 dialects plus a subset of the Pleroma/Akkoma extensions).
| Yonder | Mastodon | Akkoma/Pleroma | |
|---|---|---|---|
| Language/runtime | Rust (single binary) | Ruby + Node + optional ES | Elixir |
| Required services | Postgres + Redis | Postgres + Redis (+ ES for search) | Postgres (+ ES optional) |
| Mastodon client API | ✅ v1+v2 | ✅ (it's the reference) | ✅ |
| ActivityPub federation | ✅ | ✅ | ✅ |
| Quote posts | ✅ (both FEP-044f and FEP-e232) | ⚠️ (limited to FEP-044f) | ⚠️ (limited to FEP-e232) |
| Markdown posts | ✅ | ❌ | ✅ |
| Emoji reactions | ✅ | ❌ | ✅ |
| Webmentions | ✅ both directions | ❌ | ❌ |
| LaTeX math | ✅ server-side | ❌ (only on custom forks, and only on the frontend) | ❌ |
| Account/followers migration (both directions) | ✅ | ✅ | ✅ |
| Data export/import | ✅ both over CSV backups and API crawlers | ⚠️ only CSV backups | ⚠️ only CSV backups |
| Alternative frontends | ✅ installable and configurable on a per-user basis | ❌ | ⚠️ installable on instance level, not customizable on a user level |
| RSS/Atom feeds | ✅ | ✅ | ✅ |
| Embeddable status cards | ✅ | ❌ | ❌ |
| On-demand fetch of remote content (followers, reactions, replies) | ✅ | ❌ | ❌ |
| Admin panel | ✅ (built-in) | ✅ (built-in) | ⚠️ (as a separate frontend) |
| Battle-testing | new (v1.0.x) | a decade | ~5 years |
Quickstart
Docker
Official Docker image provided on quay.io/yonder/yonder:
docker-compose setup (with Redis, Postgres and separate worker service):
git clone https://github.com/blacklight/yonder
cd yonder
cp .env.example .env        # set PUID/PGID, domain
cp config.toml.example config.toml
docker compose up
Crate
Or grab the binary directly — it's on crates.io and in the GitHub releases:
cargo install yonder-server
# Copy and edit the configuration file
wget -O config.toml https://git.fabiomanganiello.comn/yonder/raw/branch/main/config.toml.example
yonder serve
# Separate process for workers (recommended)
yonder worker
Binary release download
VERSION="1.0.3"  # IMPORTANT: Set to the version you want
wget -O yonder.tar.xz https://github.com/blacklight/yonder/releases/download/v${VERSION}/yonder-${VERSION}-x86_64-unknown-linux-gnu.tar.xz
tar -xf yonder.tar.xz && cd yonder-${VERSION}-x86_64-unknown-linux-gnu
cp config.toml.example config.toml
./yonder serve
# Separate process for workers (recommended)
./yonder worker
Setup
Config is a single config.toml (every key also settable via YONDER_* env vars or the admin panel). Federation is on by default, registration modes are configurable, and yonder config list dumps every knob.
Create your admin user:
yonder user create --username alice --admin
Or, from your docker-compose directory:
docker compose run --rm yonder user create --username alice --admin
Open the instance, log in, and verify federation works:
curl 'https://mastodon.social/.well-known/webfinger?resource=acct:you@your.instance'
Try it
- Source: github.com/blacklight/yonder (AGPL-3.0)
- Live instance: manganiello.tech — my own Yonder instance, federated with the wider Fediverse
- API docs:
/openapi.jsonand/swagger-uion any running instance - e.g. manganiello.tech/swagger-ui
AI usage disclosure
In the following table, 🖐️ means "manual" and 🤖 means "aided by AI agents".
| Feature | 🖐️ | 🤖 |
|---|---|---|
| Initial architecture | ✅ | |
| Feature planning | ✅ | |
| Coding | ✅ | ✅ |
| Testing | ✅ | |
| Code reviews | ✅ | ✅ |
| Deployment | ✅ | |
| User documentation | ✅ | |
| Development documentation | ✅ | ✅ |
| Commit messages | ✅ | ✅ |
| Release notes | ✅ | |
| Translations | ✅ | |
| This blog article | ✅ |
Appendix: My personal federated stack
Yonder is the latest product I've built for the Fediverse.
My journey with building products for the Fediverse from scratch rather than contributing only to established projects began around the beginning of this year, as I started growing dissatisfied with the features of many established products.
My main use cases for federated platforms are:
- 📓 Blogging
- 🎵 Music publishing and federation
- 📢 General-purpose social media
And here's how my journey through self-hosted Fediverse platform went over the years.
Blogging
- Journey: WriteFreely → Madblog
- Blog article
- My instances:
Madblog was my starting point to start experimenting building software for the Fediverse.
The use-case was simple: a fully federated blogging platform that ran from a folder of Markdown files.
Single-actor instance, no support for following other users, no timelines, no admin panel, no login, no database, but full bidirectional federation based on text files and email notifications.
Music
- Journey: Funkwhale → Songhive
- Blog article
- My instance:
I built Songhive to cover many gaps I found in Funkwhale when it came to federation support, and many gaps in existing self-hosted music catalog solutions.
It's a hybrid between a music catalog with support for external sources, a platform for musicians to share and sell their content, and a music social network.
Federation-wise, it offers more features than Madblog (e.g. following users and managing timelines), but its main goal is not to provide all the features that Mastodon provides - just a sensible subset that makes it easy to share music and audio activities.
Social media
Yonder — An uncompromising ActivityPub server
A single-binary, Mastodon-compatible ActivityPub server written in Rust
Yonder — An uncompromising ActivityPub server
Reasons for yet another ActivityPub server
The beginning — Mastodon
I've been running Mastodon-compatible services for a while, starting with my first now defunct Mastodon instance at social.platypush.tech.
Mastodon is a great gateway drug for the Fediverse, but it soon started to feel tight for me.
Features often land in Mastodon only when other federated platforms have already embraced them for a while (e.g. post edits), and they often land in ways that are incompatible with what other platforms have already implemented (e.g. quotes).
And many other features that I wanted for a rich social media experience (emoji reactions, Markdown support, configurable number of profile fields, configurable maximum number of characters, configurable number of media attachments, Webmentions, backfilling of statuses and other activities from remote instances, code blocks, inline images, custom frontends, LaTeX formulas, a simpler and more complete process for account migrations...) just never landed at all.
I ended up, like many others, maintaining my own fork of Mastodon, with all the patches for features I wanted and that would have probably never been merged upstream.
At some point I realized that keeping my own fork up-to-date with all the upstream changes wasn't worth the effort, and I started to look for a better way to run Mastodon-compatible services.
Another factor that influenced my decision was Mastodon's unjustifiably high resource footprint.
My old instance used to run on a dedicated VPS with 8 GB of RAM and 500 GB of disk space.
It only had me and another active user on it.
And yet all the federated load, with all of its eager operations managed by a bloated Ruby-on-Rails + Sidekiq stack, was sufficient to choke everything, even if I regularly ran cleanups.
Down the rabbit whole — Akkoma
At some point I started looking around for federated alternatives compatible with Mastodon that had a much lower resource footprint and provided most of the features I wanted.
I soon discovered Akkoma, and I've used it for a few years as my main driver - the last instance was manganiello.eu.
Akkoma filled many of Mastodon's gaps that mattered to me:
- Markdown posts
- Configurable number of post characters
- Configurable number of profile fields
- Code blocks (no syntax highlighting though)
- Emoji reactions
- Custom frontends (but not customizable on a user level)
It still left some gaps, especially some compatibility gaps with Mastodon (indexable flag on accounts, support for Mastodon quotes, remote profile badge verification...), but for a long while I was satisfied with what it provided.
Until recently I was also the maintainer of the AUR akkoma package (now looking for a new maintainer).
But after a while I also started to feel uncomfortable with Akkoma's limitations.
Mastodon-compatible quotes were a dealbreaker, and my implementation failed to get approved upstream - ending up on the fork I ran on my instance.
Other features, like full bidirectional verification for profile badges and support for the indexable flag, also ended up living only on my fork.
Other issues, like proper compatibility with Audio activities from e.g. Funkwhale or Songhive, also made the experience less pleasant.
Akkoma however proved to show much more clemency towards my hardware resources than Mastodon did.
But the price to pay was to implement the features I wanted in a language (Elixir) that was quite exotic and unfamiliar to me (even though I ended up learning a lot from it).
I also couldn't find much documentation about e.g. Akkoma jobs or configuration.
I found Akkoma's documentation to be quite minimal in terms of content.
Understanding some configuration options or what job to run for a particular task often required me to look at the code itself.
Another issue with Akkoma was with the frontend.
I know that the default pleroma-fe can be quite polarizing, and that people either love it or hate it.
I belonged to the category of those who, no matter what, never managed to like it.
Luckily Akkoma could be configured to use alternative frontends, and I ended up liking the style of Soapbox, and even more that of its fork Mangane.
But I still felt that those frontends weren't particularly rich in terms of features, nor particularly curated around the edges.
Plus, the admin panel was an afterthough provided as a separate frontend rather than a first-class citizen like in Mastodon, and the UX was also poorly curated.
Still, the Soapbox/Mangane style ended up heavily inspiring the design of the default Yonder frontend.
Building Yonder
I started building Yonder (source code, Github mirror) a while ago, as a minimal PoC for an ActivityPub server in Rust .
It's been on a back burner on my hard drive for a while, but now I feel that it's mature enough to be my main driver on the Fediverse.
Yonder is a self-hosted, Mastodon-compatible ActivityPub server. The entire service — HTTP API, federation, streaming, media, moderation, admin panel, background jobs — is one binary. The only services it needs are PostgreSQL and Redis.
It speaks the Mastodon client API (v1 and v2), so Tusky, Ivory, Elk, Phanpy, Mona and every other Mastodon app just works when pointed at your instance.
It also implements a good subset of the Pleroma/Akkoma API dialects, which means that clients like Moshidon and other Pleroma-compatible apps can also access those features (e.g. Markdown content type for posts and custom emojis).
It speaks ActivityPub, so your users federate with Mastodon, Akkoma, Pleroma, Misskey and the rest of the Fediverse.
Name and meaning
Yonder (adv. or adj., /ˈjaʊndə/) is an Old English term for "over there". Something distant but usually within sight.
I chose it as the name for this project because it relays, together with the logo (a large circle connected to three other circles), the idea of connecting things distant but within reach.
What you get
Posting & timelines
- Rich posts in plain text or Markdown, with content warnings, polls, media attachments with editable alt text, scheduled posts, editing and saved drafts.
- Quote posts with author authorization (FEP-044f-style, with fallback to FEP-e232 Pleroma/Akkoma/Misskey compatible quotes), custom emoji reactions, replies, boosts and likes.
- Every timeline Mastodon has: home, local, federated, hashtag timelines, user-defined lists — with real-time updates over the standard Mastodon streaming WebSocket.
- Hashtags you can follow into your home feed and server-side filters (
warn/hide/blur) that apply across every timeline.
Social & federated
- Full ActivityPub federation via Pubby, with durable at-least-once delivery. I built Pubby as a general-purpose ActivityPub library that takes care of the all the plumbing behind the scenes, initially with Python bindings to power Madblog and Songhive, and it gained Rust bindings with features parity with the Python SDK in order to power Yonder - available as
pubby-sdkcrate. - Notifications in-app over WebSocket, Web Push (VAPID) and email, with per-type preferences.
- A progressive Web app (PWA) optimized for mobile and with support for native notifications.
- The bundled Web UI ships in five languages including full RTL support, with light and dark themes and custom accent colors.
- Custom emojis — per-instance emoji and emoji packs.
- Custom number of characters, custom number of profile fields, custom number of media attachments and custom number of pinned posts.
- RSS and Atom feeds for profiles, tags and lists; oEmbed/embeddable status cards.
Moderation & administration
- User-side: mutes, blocks, reports (optionally forwarded to the remote instance via
Flag), server-side content filters. - Instance-side: user limiting and suspension, domain blocks, federation relays, and a comprehensive admin panel delivered as a first-class citizen.
- Every registration policy:
open,invite-only,approval-requiredorclosed.
Platform
- One single Rust binary — stack:
axum,sqlx,tokio. - OAuth2 provider with authorization-code + PKCE, device flow, and scoped revocable API tokens.
- Pluggable frontends: the bundled Vue 3 SPA is just the default; alternative frontends can be installed alongside it. Users can pick their favourite frontend, preferences are stored in the browser session.
- OpenAPI 3 spec at
/openapi.jsonwith bundled Swagger UI. - Safety defaults: argon2id passwords, SSRF-guarded remote fetches, Redis-backed rate limits, TOTP two-factor.
What's new
Account migration
Account migration is a first-class feature: moving an account to or from another server, followers and all, is a supported flow, compatible with Mastodon and Akkoma.
On top of that, Yonder supports importing activities from the old account in two ways:
- Standard CSV import/export (compatible with Mastodon/Pleroma/Akkoma)
- OAuth2-authenticated API fetches.
You login to your old account through Yonder's interface, you pick what you want to import from your old account (including private messages, likes, boosts, replies, etc.), click "Start remote import", and everything from your old account will be copied over - as a native activity that originated from the new account, with the original timestamps respected.
The user can also decide whether the imported activities will fan out to federated instances or only be stored on the local database - prevents avoidable federation noise over imports, the activities can be selectively federated by simply boosting them or editing an old post.
The only thing that Yonder doesn't support is importing received likes, boosts and replies - for the simple reason that it doesn't want to forge federated activities or rewire threads in ways that don't reflect what other instances see.
The UX of the account migration flow has also been re-thought as a step-by-step process (connecting the old account over OAuth2, importing the data over API crawlers or CSV backups, reviewing the import process, creating an alias and moving followers), making the process much more intuitive and mistakes harder.
See the full federated picture all the time
One of the most confusing (and often infuriating) things about the Fediverse is that what you see on your local instance is often a very small subset of what's actually available on the Fediverse (unless you are on a large instance like mastodon.social, and even in that case many activities from the fringes of the Fediverse are lost).
Your instance only receives what its peers send to it. And an instance's peers depend on who your users follow, which relays you wired your instance to, and who your users interact with.
This has an unintended consequence: that content that never reaches your instance is invisible to you. Unless you trigger an explicit fetch, e.g. through a search query or some import job. And even then, you probably won't see a lot of likes, boosts and replies a remote activity has received, nor the real number of followers of a user.
Yonder solves this problem by adding a couple of new endpoints to the standard Mastodon API, and slightly modifying how some of the existing endpoints behave in order to maintain back-compatibility with existing apps.
/api/v1/accounts/{id}/sync_remote. This allows users to explicitly sync the latest<n>activities from the account{id}from the remote instance to the local database. If your Mastodon instance sees an account for the first time, and no local users follow that account, their timeline will probably appear empty, and they will show as having zero followers/followed accounts. Yonder fixes this visibility gap by adding a "Sync with<remote-instance>" button next to remote profiles, which triggers a remote fetch for their next<n>activities.- Followers and followed accounts are also synchronized with the remote instance, so you see the actual numbers. Upon calls to the
/followersendpoint, the list is lazily fetched and you can navigate it from your local instance - without having to open the original profile URL to see the actual numbers. /api/v1/statuses/{id}/fetch_remote_context. This endpoint is called by the Yonder frontend whenever you expand a post that belongs to a remote thread. What it does is to fetch behind the scenes all the statuses that belong to the same parent line, with a default maximum depth of 20. This, in my opinion, matches the expected behavior from a social app user. If I see a comment from a friend on another thread and I click on it, the most relevant thing I want to see is the direct path of statuses from the root of the thread down to the status I clicked on, plus the next 2-3 direct children. The client ends up seeing exactly the same context as the instance of the post's author. This is back-compatible also with existing Mastodon apps - calls to the/contextendpoint will trigger/fetch_remote_contextbehind the scenes if needed, and a refresh of the status 2-3 seconds later should show all the expanded remote posts in that path. Siblings and descendants from other paths are not fetched by default, but they are fetched if the user expands statuses on those paths. This approach means that fetches of remote threads provide a much more complete picture than that provided by Mastodon by default (you get to see exactly the same view as the author of that post, not only the subset explicitly send to your instance), while simultaneously being more efficient than what e.g. Mastodon does (fetch overhead is capped by the depth of the path, set to 20 by default, instead of trying to eagerly fetch the whole tree with no boundaries).
Another handful of useful API extensions
POST/DELETE /api/v1/accounts/{id}/subscribe: subscribe/unsubscribe to an account's activities without publicly following them.GET /api/v1/trends/tags: browse global or local trending hashtags, with support for pagination and time ranges.POST /api/v1/admin/accounts/{id}/reset_password: programmatically send a user password reset link directly to their email.POST /api/v1/admin/statuses/{id}/action: apply granular moderation to individual statuses (delete, mark as sensitive, add content warning).
Trending hashtags
This is something that for some reason Mastodon removed at some point, but that I find very useful.
Yonder makes it easy not only to follow hashtags, but to have a view of all the hashtags that are trending over the local instance or over all the known Fediverse, over a given period of time, and with support for pagination.
Direct messages as real conversations
Direct messages in Yonder are real conversations, not just an ungrouped timeline of cards with a lock on them.
This is similar to what users expects by social networks like X, Facebook or Instagram - private messages are not a timeline, they are grouped conversations, and it should be easy to find a private message from a month ago even if you received hundreds of messages on a single unrelated conversation in the meantime.
Webmentions
Webmentions are first-class citizens supported in both directions.
What this means is that:
- If a blog or federated actor
example.blogthat supports Webmentions posts a link toexample.social/status/123,example.socialwill process the Webmention and render it as a normal reply or reaction. The Webmentions actor will also be transparently rendered as a virtual user on the platform. - If you link
example.blogin a post onexample.social, andexample.blogsupports Webmentions, then the target will receive a Webmention request, and your social activity may be natively rendered under the blog article.
Webmentions are powered by my webmentions library - which, just like Pubby, was initially built in Python to support Webmentions on Madblog and Songhive, and then ported to Rust with features parity with the Python SDK - available as webmentions-sdk crate.
LaTeX
Instances like mathstodon.xyz run their own forks of Mastodon with support for LaTeX formulas.
But they use MathJax, which means that formulas are only rendered on the frontend, and only if you see them from that instance.
Yonder goes one step further and it adds rendering of LaTeX formulas directly on the backend.
You can provide your rendering script, set math.enabled = true in your configuration, and set math.command to your LaTeX rendering command.
Any command that takes the LaTeX formula on the stdin and returns an image on stdout works.
The repository ships a latex-math-render.sh script that is already compatible with tectonic and pdflatex.
Being rendered on the backend, the formulas are also rendered on clients that don't support frontend rendering through MathJax.
If the server or the client support inline images (e.g. Phanpy), then formulas will be rendered inline.
If it supports math-type attachments, then the formulas will be rendered at the bottom of the post.
Otherwise, they will graciously fall back to image attachments, with LaTeX-style references ((1), (2)...) as links in the post.
Inline images
Yonder supports inline images via standard Markdown:

Embeddables
Embed your posts in blog, Websites and anywhere on the Web. Click on the context menu of a post, select "Embed", and copy the snippet:
<div class="yonder-embed" data-status="{status-id}">
  <a href="https://{instance}/statuses/{status-id}/embed">Post by @{user}@{instance}</a>
</div>
<script async src="https://{instance}/embed.js" charset="utf-8"></script>
<noscript>
  <iframe src="https://{instance}/statuses/{status-id}/embed" width="100%" height="400" frameborder="0" loading="lazy" title="Post by @{user}@{instance}" />
</noscript>
An example:
Reactions to the status are fetched from the instance, if the user updates their status the referring page will update as well. If the status is deleted, it will also be deleted from the referring page. And Webmentions towards the Yonder target will also be processed if supported by the referring page, so the referring page will also be shown under the thread as a federated reply.
How it compares
I want to be honest here rather than hype-y, because "yet another Mastodon-compatible server" deserves scrutiny.
A feature matrix would be the natural way to do this, but matrices are painful to read on a phone, so here's a plain-language summary of where each implementation actually stands (as of late 2026). All of them speak ActivityPub and the Mastodon client API (Yonder implements both the v1 and v2 dialects plus a subset of the Pleroma/Akkoma extensions).
| Yonder | Mastodon | Akkoma/Pleroma | |
|---|---|---|---|
| Language/runtime | Rust (single binary) | Ruby + Node + optional ES | Elixir |
| Required services | Postgres + Redis | Postgres + Redis (+ ES for search) | Postgres (+ ES optional) |
| Mastodon client API | ✅ v1+v2 | ✅ (it's the reference) | ✅ |
| ActivityPub federation | ✅ | ✅ | ✅ |
| Quote posts | ✅ (both FEP-044f and FEP-e232) | ❌ (limited to FEP-044f) | ❌ (limited to FEP-e232) |
| Markdown posts | ✅ | ❌ | ✅ |
| Emoji reactions | ✅ | ❌ | ✅ |
| Webmentions | ✅ both directions | ❌ | ❌ |
| LaTeX math | ✅ server-side | ❌ (only on custom forks, and only on the frontend) | ❌ |
| Account/followers migration (both directions) | ✅ | ✅ | ✅ |
| Data export/import | ✅ both over CSV backups and API crawlers | ⚠️ only CSV backups | ⚠️ only CSV backups |
| Alternative frontends | ✅ installable and configurable on a per-user basis | ❌ | ⚠️ installable on instance level, not customizable on a user level |
| RSS/Atom feeds | ✅ | ✅ | ✅ |
| On-demand fetch of remote content (followers, reactions, replies) | ✅ | ❌ | ❌ |
| Admin panel | ✅ (built-in) | ✅ (built-in) | ⚠️ (as a separate frontend) |
| Battle-testing | new (v1.0.x) | a decade | ~5 years |
Quickstart
Docker
Official Docker image provided on quay.io/yonder/yonder:
docker-compose setup (with Redis, Postgres and separate worker service):
git clone https://github.com/blacklight/yonder
cd yonder
cp .env.example .env        # set PUID/PGID, domain
cp config.toml.example config.toml
docker compose up
Crate
Or grab the binary directly — it's on crates.io and in the GitHub releases:
cargo install yonder-server
# Copy and edit the configuration file
wget -O config.toml https://git.fabiomanganiello.comn/yonder/raw/branch/main/config.toml.example
yonder serve
# Separate process for workers (recommended)
yonder worker
Binary release download
VERSION="1.0.3"  # IMPORTANT: Set to the version you want
wget -O yonder.tar.xz https://github.com/blacklight/yonder/releases/download/v${VERSION}/yonder-${VERSION}-x86_64-unknown-linux-gnu.tar.xz
tar -xf yonder.tar.xz && cd yonder-${VERSION}-x86_64-unknown-linux-gnu
cp config.toml.example config.toml
./yonder serve
# Separate process for workers (recommended)
./yonder worker
Setup
Config is a single config.toml (every key also settable via YONDER_* env vars or the admin panel). Federation is on by default, registration modes are configurable, and yonder config list dumps every knob.
Create your admin user:
yonder user create --username alice --admin
Or, from your docker-compose directory:
docker compose run --rm yonder user create --username alice --admin
Open the instance, log in, and verify federation works:
curl 'https://mastodon.social/.well-known/webfinger?resource=acct:you@your.instance'
Try it
- Source: github.com/blacklight/yonder (AGPL-3.0)
- Live instance: manganiello.tech — my own Yonder instance, federated with the wider Fediverse
- API docs:
/openapi.jsonand/swagger-uion any running instance - e.g. manganiello.tech/swagger-ui
AI usage disclosure
In the following table, 🖐️ means "manual" and 🤖 means "aided by AI agents".
| Feature | 🖐️ | 🤖 |
|---|---|---|
| Initial architecture | ✅ | |
| Feature planning | ✅ | |
| Coding | ✅ | ✅ |
| Testing | ✅ | |
| Code reviews | ✅ | ✅ |
| Deployment | ✅ | |
| User documentation | ✅ | |
| Development documentation | ✅ | ✅ |
| Commit messages | ✅ | ✅ |
| Release notes | ✅ | |
| Translations | ✅ | |
| This blog article | ✅ |
Appendix: My personal federated stack
Yonder is the latest product I've built for the Fediverse.
My journey with building products for the Fediverse from scratch rather than contributing only to established projects began around the beginning of this year, as I started growing dissatisfied with the features of many established products.
My main use cases for federated platforms are:
- 📓 Blogging
- 🎵 Music publishing and federation
- 📢 General-purpose social media
And here's how my journey through self-hosted Fediverse platform went over the years.
Blogging
- Journey: WriteFreely → Madblog
- Blog article
- My instances:
Madblog was my starting point to start experimenting building software for the Fediverse.
The use-case was simple: a fully federated blogging platform that ran from a folder of Markdown files.
Single-actor instance, no support for following other users, no timelines, no admin panel, no login, no database, but full bidirectional federation based on text files and email notifications.
Music
- Journey: Funkwhale → Songhive
- Blog article
- My instance:
I built Songhive to cover many gaps I found in Funkwhale when it came to federation support, and many gaps in existing self-hosted music catalog solutions.
It's a hybrid between a music catalog with support for external sources, a platform for musicians to share and sell their content, and a music social network.
Federation-wise, it offers more features than Madblog (e.g. following users and managing timelines), but its main goal is not to provide all the features that Mastodon provides - just a sensible subset that makes it easy to share music and audio activities.
Social media
A science, engineering and music geek who likes to build open-source things that solve problems.
🖥️ Tech
I have been a citizen of the Internet since the early 2000s, and a passionate self-hoster since about day 1 (my adventure started with hosting my personal Website and phpBB a spare Pentium 1 under my bed, with Slackware Linux installed from floppy disks).
Some of my tech contributions, in no particular order.
📚 Academic
-
Computer Vision with Maker Tech (ISBN 978-1-4842-6820-9), published by Springer in 2021. A hands-on introduction to machine learning and computer vision using DIY tech, RaspberryPis and thermal cameras.
-
Framework and Models for Multistep Attack Detection, 2011, published in the International Journal of Security and Its Applications.
-
Identification of correlated network intrusion alerts, 2011, published by IEEE in the Third International Workshop on Cyberspace Safety and Security.
-
Multistep Attack Detection and Alert Correlation in Intrusion Detection Systems, 2011, published in Information Security and Assurance (ISA 2011).
-
Machine learning algorithms for clustering and correlating security alerts in Intrusion Detection Systems, 2010, my Master's Thesis.
💼 Professional
A non-exhaustive list of some of my employers over the years, in no particular order:
- ✈️ Booking.com (current employer)
- 💵 Adyen
- 🚢 Flexport
- ✨ expert.ai
🔓 Open-Source
| 📂 Project | ✏️ Description | |
|---|---|---|
⚙️ Platypush

|
Platypush is an ambitious general-purpose platform for automation, IoT, media streaming and more that has kept me busy since 2015. Or, as some call it, Home Assistant's geeker brother. It provides hundreds of supported integrations, covering everything from MQTT to cameras, from smart lights to media services, from Arduino and ESP8266 devices to machine learning models, from messaging platforms to calendars, and more. It also enables users to configure arbitrarily complex routines on events through either Python or YAML event handlers. A powerful web extension that allows you to run routines directly from your browser is also available. | |
📢 Yonder

|
A powerful ActivityPub server in Rust, bundled in a single binary. Fully compatible both with Mastodon and Pleroma/Akkoma - and it aims to always be compatible with them. Among the unique perks:
| |
▶️ Songhive

|
Songhive is a general-purpose platform for music streaming, sales, collection uploads and syncs, with support for ActivityPub, Webmentions, Subsonic API-compatible music players, multiple streaming services and storages, Mopidy, podcasts, live streaming and more. | |
📖 Madblog

|
Madblog is a powerful blogging engine that natively supports Webmentions and federation over ActivityPub. It's a strongly opinionated platform based on simplicity. No databases, no JavaScript, no write APIs, no authentication, no migrations: your blog is a folder of Markdown files. You can run Madblog on top of an Obsidian vault, a Nextcloud shared directory, a git clone, and much more. It is also the blogging platform powering the page you are reading right now. |
|
📍 GPSTracker

|
A full-featured self-hosted Web app to store your GPS data points, render them on timelines, search for activities by geographical area or time, and run statistics on them. A crossing between Google Maps Timeline and Foursquare's Swarm, but self-hosted and Web-based. | |
✏️ nvim-http

|
A plugin to run HTTP request files in nvim. Inspired by (and compatible with) the HTTP requests plugins provided by JetBrains and VSCode. | |
🌐 Pubby

|
A batteries-included library with a simple API that allows you to easily plug ActivityPub support into your website. It power's Madblog's ActivityPub integration. | |
🔗 Webmentions

|
A batteries-included library with a simple API that allows you to easily plug Webmentions support into your website. It power's Madblog's Webmentions integration. | |
🎤 Micmon

|
A general-purpose Python library and set of tools for audio detection through Fourier analysis and Tensorflow. | |
∿ Theremin

|
A contactless, hands-in-air digital implementation of a Theremin musical instrument through a Leap Motion device. | |
👣 Snort_AIPreproc

|
A machine learning module for the intrusion detection system Snort that removes the noise from the logs, clusters similar alerts together, finds common causal links between alerts and predicts the next step in a multi-step attack scenario. | |
fsom

|
A C library for managing Self-Organizing Maps. | |
fkmeans

|
A C library to perform K-means clustering. | |
🗣️ Voxifera

|
(Probably) one of the earliest examples of voice assistants I'm aware of - I built it back in 2008 but it's largely discontinued now. |
📑 Blogs
- Personal blog (also federated at
@fabio@manganiello.blog) - Platypush blog (also federated at
@blog@platypush.tech)
🏆 Awards
- Hackernoon 2020 contributor of the year (IoT)
- Hackernoon 2022 contributor of the year (Distributed Systems)
- Hackernoon 2022 contributor of the year (Proof of Stake)
🎵 Music
I occasionally perform and record music - mostly guitar-based, with a few excursions into electronic, orchestral and ethnic music.
You can check my releases on:
- @fabio@manganiello.music, which you can also follow through Mastodon or other Fediverse-based implementations (it's federated through Songhive)
- Spotify
- Tidal
✊ Activism
Technology
The formation of giant tech oligopolies with such a huge influence over society is a spectacular systemic failure that must be undone at all costs, and regulation must prevent the conditions that lead to such a state.
You'll probably find me at some somewhere advocating for open-source, open data access, privacy, decentralization and self-hosted solutions. Or talk about #platypush or #madblog.
I have an academic and professional background rooted in big data and machine learning, and I embrace #ai as a powerful tool in our hands. But I strongly oppose the disproportionate concentration of power, the unaccountability and the rotten business models that drive much of today's AI.
Politics and society
- Antifascist to the core.
- Billionaires and oligopolies are a threat to democracy.
- Supporting self-determination against all forms of colonialism, imperialism and racism.
🇺🇦 🇵🇸 🇹🇼 🇬🇱 🇸🇩
I am part of the gaza-verified.org initiative, whose purpose is to help people from Gaza being verified and onboarded on social media and protect their voices on the Internet.
I have built the gaza-verified archive as an effort to permanently archive their voices and memories.
🌳 Life
Italian based in the Netherlands who is still struggling with his Dutch.
Among the things I like to do when not at a keyboard or a guitar:
- 🛹 Roll my skate
- 🏄 Chase waves
- 🍺 Enjoy craft beer
- 👪 Raise a new geek
📧 Contacts
| 🗣️ ActivityPub | @fabio@manganiello.tech |
| 💬 Matrix | @fabio:manganiello.tech |
| 💬 XMPP | fabio@manganiello.tech |
| fabio@manganiello.tech |
I started working on Madblog a few years ago.
I wanted a simple blogging platform that I could run from my own Markdown files. No intermediaries. No bloated UI. No JavaScript. No databases and migration scripts. No insecure plugins. Just a git folder, an Obsidian vault or a synchronized SyncThing directory, and the ability to create and modify content by simply writing text files, wherever I am.
Drop a Markdown file in the directory, and it's live. Edit it, and the changes propagate. Delete it, and it's gone.
It's been running my personal blog and the Platypush blog for a while now.
With the new release, #madblog now gets a new superpower: it supports federation, interactions and comments both through:
- Webmentions - already implemented some weeks ago, you can also check out the previous blog article
- ActivityPub
Webmentions allow your site to mention and be mentioned by other sites that also implement them - like any WordPress blog with the Webmention plugin, or link aggregators like Lemmy or HackerNews. Interactions with any of your pages will be visible under them.
#activitypub support allows Madblog to fully federate with Mastodon, Pleroma, Misskey, Friendica or any other #fediverse instance. It turns your blog into a federated handle that can be followed by anyone on the Fediverse. It gives you the ability to mention people on the Fediverse directly from your text files, and get replies to your articles directly from Mastodon, get your articles boosted, shared and quoted like any other Mastodon post.
Demos
These blogs are powered by Madblog:
- blog.fabiomanganiello.com — Fediverse handle: @fabio@manganiello.blog
- blog.platypush.tech — Fediverse handle: @blog@platypush.tech
You can follow them from Mastodon (or any other Fediverse client), reply to articles directly from your instance, boost them, or quote them. You can also interact via Webmentions: link to an article from your own site, and if your site supports Webmentions, the mention will show up as a response on the original post. These blogs also have a Guestbook — mention the blog's Fediverse handle or send a Webmention to the home page, and your message appears on a public guest registry.
How Does It Compare?
If you've looked into federated blogging before, you've likely come across a few options:
-
WriteFreely is probably the closest alternative — a minimalist, Go-based platform with ActivityPub support. It's well-designed, but it uses a database (SQLite or MySQL), has its own (very minimal) editor, and doesn't support Webmentions. Additionally, it lacks many features that are deal-breakers for me.
- No export of all the content to Markdown, nor ability to run my blog from my Nextcloud Notes folder or Obsidian vault.
- No support for LaTeX or Mermaid diagrams.
- No support for federated interactions - any interaction with your articles on the Fediverse is simply lost.
- The UI is minimalist and not necessarily bad, but not even sufficiently curated for something like a blog (narrow width, Serif fonts not optimized for legibility, the settings and admin panels are a mess...).
- No support for moderation / content blocking.
- No support for federated hashtags.
-
WordPress with ActivityPub and Webmention plugins can technically do what Madblog does, but it's a full CMS with a database, a theme engine, a plugin ecosystem, and a much larger attack surface. If all you need is a blog, it's overkill.
-
Plume and Friendica offer blogging with federation, but they're full social platforms, not lightweight publishing tools.
Madblog sits in a different niche: it's closer to a static-site generator that happens to speak federation protocols. It implements a workflow like "write Markdown, push to server, syndicate everywhere".
Getting Started
Docker Quickstart
mkdir -p ~/madblog/markdown
cat <<EOF > ~/madblog/markdown/hello-world.md

This is my first post on [Madblog](https://git.fabiomanganiello.com/madblog)!
EOF

docker run -it \
  -p 8000:8000 \
  -v "$HOME/madblog:/data" \
  quay.io/blacklight/madblog
Open http://localhost:8000. That's it — you have a blog.
The default Docker image (quay.io/blacklight/madblog) is a minimal build (< 100 MB) that includes everything except LaTeX and Mermaid rendering. If you need those, build the full image from source:
git clone https://git.fabiomanganiello.com/madblog
cd madblog
docker build -f docker/full.Dockerfile -t madblog .
See the full Docker documentation for details on mounting config files and ActivityPub keys.
Markdown structure
Since there's no database or extra state files involved, the metadata of your articles is also stored in Markdown.
Some things (like title, description) can be inferred from the file name, headers of your files etc., creation date defaults to the creation timestamp of the file and author and language are inherited from your config.yaml.
A full customized header would look like this:
---
title: Title of the article
description: Short description of the content
image: /img/some-header-image.png
author: Author Name <https://author.me>
author_photo: https://author.me/avatar.png
language: en-US
published: 2022-01-01
---

...your Markdown content...
Key Configuration
Madblog reads configuration from a config.yaml in your content directory. Every option is also available as an environment variable with a MADBLOG_ prefix — handy for Docker or CI setups.
A minimal config to get started:
title: My Blog
description: Thoughts on tech and life
link: https://myblog.example.com
author: Your Name
Or purely via environment variables:
docker run -it \
  -p 8000:8000 \
  -e MADBLOG_TITLE="My Blog" \
  -e MADBLOG_LINK="https://myblog.example.com" \
  -e MADBLOG_AUTHOR="Your Name" \
  -v "$HOME/madblog:/data" \
  quay.io/blacklight/madblog
See config.example.yaml for the full reference.
It is advised to keep all of your Markdown content under
<data-dir>/markdown, especially if you enable federation, in order to keep the Markdown folder tidy from all the auxiliary files generated by Madblog.
Webmentions
Webmentions are the IndieWeb's answer to trackbacks and pingbacks — a W3C standard that lets websites notify each other when they link to one another. Madblog supports them natively, both inbound and outbound.
When someone links to one of your articles from a Webmention-capable site, your blog receives a notification and renders the mention as a response on the article page. Going the other way, when you link to an external URL in your Markdown and save the file, Madblog automatically discovers the target's Webmention endpoint and sends a notification — no manual step required. All mentions are stored as Markdown files under your content directory (mentions/incoming/<post-slug>/), so they're version-controllable and easy to inspect.
You can enable pending-mode for moderation (webmentions_default_status: pending), or use the blocklist/allowlist system to filter sources by domain, URL, or regex. Webmentions are enabled by default — if you're running Madblog locally for testing, set enable_webmentions: false to avoid sending real notifications to external sites.
ActivityPub Federation
ActivityPub is the protocol that powers the Fediverse — Mastodon, Pleroma, Misskey, and hundreds of other platforms. Madblog implements it as a first-class feature: enable it, and your blog becomes a Fediverse actor that people can follow, reply to, boost, and quote.
Enable it in your config:
enable_activitypub: true
activitypub_username: blog
activitypub_private_key_path: /path/to/private_key.pem
Madblog will generate an RSA keypair on first start if you don't provide one. Once enabled, your blog gets a Fediverse handle (@blog@yourdomain.com), a WebFinger endpoint for discovery, and a full ActivityPub actor profile. New and updated articles are automatically delivered to all followers' timelines.
Here's what federation looks like in practice:
- Receiving mentions: when someone mentions your blog's Fediverse handle in a public post (not as a reply to a specific article), the mention shows up on your Guestbook page.
- Receiving replies, likes, boosts, and quotes: interactions targeting a specific article are rendered below that article — replies as threaded comments, likes/boosts/quotes as counters and cards. All stored as JSON files on disk.
- Sending mentions: just write the fully-qualified handle in your Markdown (
@alice@mastodon.social) and save the file. Madblog resolves the actor via WebFinger and delivers a proper ActivityPubMentiontag — the mentioned user gets a notification on their instance. - Federated hashtags: hashtags in your articles (
#Python,#Fediverse) are included as ActivityPubHashtagtags in the published object. Followers who track those hashtags on their instance will see your posts in their filtered feeds. -
Custom profile fields: configure additional profile metadata (verified links, donation pages, git repos) that show up on your actor's profile as seen from Mastodon and other Fediverse clients:
yaml
activitypub_profile_fields:
  Git repository: <https://git.example.com/myblog>
  Donate: <https://liberapay.com/myprofile>
The federation layer also exposes a read-only subset of the Mastodon API, so Mastodon-compatible clients and crawlers can discover the instance, look up the actor, list published statuses, and search for content — with no extra configuration.
Madblog also supports advanced ActivityPub features like split-domain setups (e.g. your blog at blog.example.com but your Fediverse handle at @blog@example.com), configurable object types (Note for inline rendering on Mastodon vs. Article for link-card previews), and quote policies (FEP-044f, so Mastodon users can quote your articles too).
LaTeX and Mermaid
Madblog supports server-side rendering of LaTeX equations and Mermaid diagrams directly in your Markdown files — no client-side JavaScript required.
LaTeX uses latex + dvipng under the hood. Inline expressions use conventional LaTeX markers:
The Pythagorean theorem states that \(c^2 = a^2 + b^2\).

$$
E = mc^2
$$
Mermaid diagrams use standard fenced code blocks. Both light and dark theme variants are rendered at build time and switch automatically based on the reader's color scheme:
 ```mermaid
 graph LR
     A[Write Markdown] --> B[Madblog renders it]
     B --> C[Fediverse sees it]
 ```
Install Mermaid support with pip install "madblog[mermaid]" or use the full Docker image. Rendered output is cached, so only the first render of each block is slow.
Tags and Categories
Tag your articles with hashtags — either in the metadata header or directly in the body text:
---
tags: "#python, #fediverse, #blogging"
---

# My Article

This post is about #Python and the #Fediverse.
Madblog builds a tag index at /tags, with per-tag pages at /tags/<tag>. Hashtags from incoming Webmentions are also indexed. Folders in your content directory act as categories — if you organize files into subdirectories, the home page groups articles by folder.
Feed Syndication
Madblog generates both RSS and Atom feeds at /feed.rss and /feed.atom. You can control whether feeds include full article content or just descriptions (short_feed: true), and limit the number of entries (max_entries_per_feed: 10). limit and offset parameters are also supported for pagination.
Aggregator Mode
Madblog can also pull in external RSS/Atom feeds and render them alongside your own posts on the home page — useful for affiliated blogs, or even as a self-hosted feed reader:
external_feeds:
  - https://friendsblog.example.com/feed.atom
  - https://colleaguesblog.example.com/feed.atom
Guestbook
The guestbook (/guestbook) is a dedicated page that aggregates public interactions — Webmentions targeting the home page and Fediverse mentions of your blog actor that aren't replies to specific articles. Think of it as a public guest registry, or a lo-fi comment section for your blog as a whole. Visitors can leave a message by mentioning your Fediverse handle or sending a Webmention. It can be disabled via enable_guestbook=0.
View Modes
The home page supports three layouts:
cards(default) — a responsive grid of article cards with imageslist— a compact list with titles and datesfull— a scrollable, WordPress-like view with full article content inline
Set it in your config (view_mode: cards) or override at runtime with ?view=list.
Moderation
Madblog ships with a flexible moderation system that applies to both Webmentions and ActivityPub interactions. You can run in blocklist mode (reject specific actors) or allowlist mode (accept only specific actors), with pattern matching by domain, URL, ActivityPub handle, or regex:
blocked_actors:
  - spammer.example.com
  - "@troll@evil.social"
  - /spam-ring\.example\..*/
Moderation rules also apply retroactively — interactions already stored are filtered at render time. Blocked ActivityPub followers are excluded from fan-out delivery and hidden from the public follower count, but their records are preserved so they can be automatically reinstated if you change your rules.
Email Notifications
Configure SMTP settings and Madblog will notify you by email whenever a new Webmention or ActivityPub interaction arrives — likes, boosts, replies, mentions, and quotes:
author_email: you@example.com
smtp_server: smtp.example.com
smtp_username: you@example.com
smtp_password: your-password
Progressive Web App
Madblog is installable as a PWA, with offline access and a native-like experience on supported devices. A service worker handles stale-while-revalidate caching with background sync for retries.
Raw Markdown Access
Append .md to any article URL to get the raw Markdown source:
https://myblog.example.com/article/my-post.md
Useful for readers who prefer plain text, or for tools that consume Markdown directly.
Reusable Libraries
Two key subsystems of Madblog have been extracted into standalone, reusable Python libraries. If you're building a Python web application and want to add decentralized federation support, you can use them directly — no need to adopt Madblog itself.
Webmentions
Webmentions is a general-purpose Python library for sending and receiving Webmentions. It comes with framework adapters for FastAPI, Flask, and Tornado, pluggable storage backends (SQLAlchemy or custom), filesystem monitoring for auto-sending mentions when files change, full microformats2 parsing, and built-in HTML rendering for displaying mentions on your pages.
Adding Webmentions to a FastAPI app:
from fastapi import FastAPI
from webmentions import WebmentionsHandler
from webmentions.storage.adapters.db import init_db_storage
from webmentions.server.adapters.fastapi import bind_webmentions

app = FastAPI()
storage = init_db_storage(engine="sqlite:////tmp/webmentions.db")
handler = WebmentionsHandler(storage=storage, base_url="https://example.com")
bind_webmentions(app, handler)
That's it — your app now has a /webmentions endpoint for receiving mentions,
a Link header advertising it on every response, and a storage layer for
persisting them. See the
full documentation
for details on sending mentions, custom storage, moderation, and rendering.
Pubby
Pubby is a general-purpose Python library for adding ActivityPub federation to any web application. It handles inbox processing, outbox delivery with concurrent fan-out, HTTP Signatures, WebFinger/NodeInfo discovery, interaction storage, a Mastodon-compatible API, and framework adapters for FastAPI, Flask, and Tornado.
Adding ActivityPub to a FastAPI app:
from fastapi import FastAPI
from pubby import ActivityPubHandler, Object
from pubby.crypto import generate_rsa_keypair
from pubby.storage.adapters.db import init_db_storage
from pubby.server.adapters.fastapi import bind_activitypub

app = FastAPI()
storage = init_db_storage("sqlite:////tmp/pubby.db")
private_key, _ = generate_rsa_keypair()

handler = ActivityPubHandler(
    storage=storage,
    actor_config={
        "base_url": "https://example.com",
        "username": "blog",
        "name": "My Blog",
        "summary": "A blog with ActivityPub support",
    },
    private_key=private_key,
)

bind_activitypub(app, handler)

# Publish a post to all followers
handler.publish_object(Object(
    id="https://example.com/posts/hello",
    type="Note",
    content="<p>Hello from the Fediverse!</p>",
    url="https://example.com/posts/hello",
    attributed_to="https://example.com/ap/actor",
))
Optionally, you can also expose a Mastodon-compatible API so that Mastodon clients and crawlers can discover your instance and browse statuses:
from pubby.server.adapters.fastapi_mastodon import bind_mastodon_api

bind_mastodon_api(
    app,
    handler,
    title="My Blog",
    description="A blog with ActivityPub support",
)
Both libraries follow the same design philosophy: provide the protocol plumbing so you can wire it into your existing application with minimal ceremony. Storage is pluggable (SQLAlchemy, file-based, or bring-your-own), framework binding is a single function call, and the core logic is framework-agnostic. See the full documentation for Pubby and Webmentions.
Links
Madblog is open-source under the AGPL-3.0-only license. The source code, issue tracker, and full documentation are available at git.fabiomanganiello.com/madblog.
https://www.google.com.gt/share.google?q=fYnsQExDVeKyJaVd1&RDJM586lrHcyA
@SophiaFree @AGreatSound @anyimv @Links_Herz @schlojj @ekkologie @schelter87 @Berater_1 @Silja @Djuna @somei__bot @sarenthar @amunizp @Naseemhv @SamHartle @shifudesu @spydoggie @trevorflowers @TomatoSoup @kingu@mstdn.social @micha @bluepurplerain @Kit @steinstory @alexvdbrandhof @negentropy @yoranuko3 @ansh_blue @11220 @hat0da @Pikachu @Pixelscapes @christiansagt @mayblossom @maslanang @blog @anamitra @sallyyii1_5566 @xfnw @KholBluR @bloomnobly @ALISA_Lexington @BronseAsia

Dove trovare esempi di Madblog? Fabio Manganiello al @devconf
- blog.fabiomanganiello.com, il blog di Fabio
- Handle: @fabio@manganiello.blog
- blog.platypush.tech, il blog di Platypush (il mio progetto principale)
- Handle: @blog
- fabiomanganiello.com, il sito Web principale di @fabio@manganiello.eu
- che utilizza Madblog in modalità aggregatore, e ritorna articoli da tutti iblog di Fabio
A science, engineering and music geek who likes to build open-source things that solve problems.
🖥️ Tech
I have been a citizen of the Internet since the early 2000s, and a passionate self-hoster since about day 1 (my adventure started with hosting my personal Website and phpBB a spare Pentium 1 under my bed, with Slackware Linux installed from floppy disks).
Some of my tech contributions, in no particular order.
📚 Academic
-
Computer Vision with Maker Tech (ISBN 978-1-4842-6820-9), published by Springer in 2021. A hands-on introduction to machine learning and computer vision using DIY tech, RaspberryPis and thermal cameras.
-
Framework and Models for Multistep Attack Detection, 2011, published in the International Journal of Security and Its Applications.
-
Identification of correlated network intrusion alerts, 2011, published by IEEE in the Third International Workshop on Cyberspace Safety and Security.
-
Multistep Attack Detection and Alert Correlation in Intrusion Detection Systems, 2011, published in Information Security and Assurance (ISA 2011).
-
Machine learning algorithms for clustering and correlating security alerts in Intrusion Detection Systems, 2010, my Master's Thesis.
💼 Professional
A non-comprehensive list of my employers over the years, in no particular order:
- ✈️ Booking.com (current employer)
- 💵 Adyen
- 🚢 Flexport
- ✨ expert.ai
🔓 Open-Source
| 📂 Project | ✏️ Description | |
|---|---|---|
|
⚙️ Platypush
|
Platypush is an ambitious general-purpose platform for automation, IoT, media streaming and more that has kept me busy since 2015. Or, as some call it, Home Assistant's geeker brother. It provides hundreds of supported integrations, covering everything from MQTT to cameras, from smart lights to Google services, from Arduino and ESP8266 devices to machine learning models, from social and messaging platforms to calendars, and more. to one another through a consistent UI and backend interface. It also enables users to create arbitrary complex automation routines when events happen. It also comes with a powerful web extension. | |
|
📖 Madblog
|
Madblog is a powerful blogging engine that natively supports Webmentions and federation over ActivityPub. It's a strongly opinionated platform based on simplicity. No databases, no JavaScript, no write APIs, no authentication: your blog is a folder of Markdown files. You can run Madblog on top of an Obsidian vault, a Nextcloud shared directory, a git clone, and much more. | |
|
📍 GPSTracker
|
A full-featured self-hosted Web app to store your GPS data points, render them on timelines, search for activities by geographical area or time, and run statistics on them. A crossing between Google Maps Timeline and Foursquare's Swarm, but self-hosted and Web-based. | |
|
✏️ nvim-http
|
A plugin to run HTTP request files in nvim. Inspired by (and compatible with) the HTTP requests plugins provided by JetBrains and VSCode. | |
|
🌐 Pubby
|
A batteries-included library with a simple API that allows you to easily plug ActivityPub support into your website. It power's Madblog's ActivityPub integration. | |
|
🔗 Webmentions
|
A batteries-included library with a simple API that allows you to easily plug Webmentions support into your website. It power's Madblog's Webmentions integration. | |
|
🎤 Micmon
|
A general-purpose Python library and set of tools for audio detection through Fourier analysis and Tensorflow. | |
|
∿ Theremin
|
A contactless, hands-in-air digital implementation of a Theremin musical instrument through a Leap Motion device. | |
|
👣 Snort_AIPreproc
|
A machine learning module for the intrusion detection system Snort that removes the noise from the logs, clusters similar alerts together, finds common causal links between alerts and predicts the next step in a multi-step attack scenario. | |
|
fsom
|
A C library for managing Self-Organizing Maps. | |
|
fkmeans
|
A C library to perform K-means clustering. | |
|
🗣️ Voxifera
|
(Probably) one of the earliest examples of voice assistants I'm aware of - I built it back in 2008 but it's largely discontinued now. |
📑 Blogs
- Personal blog (also federated at
@fabio@manganiello.blog) - Platypush blog (also federated at
@blog@platypush.tech)
🏆 Awards
- Hackernoon 2020 contributor of the year (IoT)
- Hackernoon 2022 contributor of the year (Distributed Systems)
- Hackernoon 2022 contributor of the year (Proof of Stake)
🎵 Music
I occasionally perform and record music - mostly guitar-based, with a few excursions into electronic, orchestral and ethnic music.
You can check my releases on:
- @fabio@manganiello.music, which you can also follow through Mastodon or other Fediverse-based implementations (it's federated through Funkwhale)
- Spotify
- Tidal
✊ Activism
Technology
The formation of giant tech oligopolies with such a huge influence over society is a spectacular systemic failure that must be undone at all costs, and regulation must prevent the conditions that lead to such a state.
You'll probably find me at some somewhere advocating for open-source, open data access, privacy, decentralization and self-hosted solutions. Or talk about #platypush or #madblog.
I have an academic and professional background rooted in big data and machine learning, and I embrace #ai as a powerful tool in our hands. But I strongly oppose the disproportionate concentration of power, the unaccountability and the rotten business models that drive much of today's AI.
Politics and society
- Antifascist to the core.
- Always on the side of the oppressed.
- 🇺🇦 🇵🇸 🇹🇼 🇬🇱 🇸🇩 Supporting self-determination against all forms of colonialism, imperialism and racism.
I am part of the gaza-verified.org initiative, whose purpose is to help people from Gaza being verified and onboarded on social media and protect their voices.
I have built the gaza-verified archive as an effort to permanently archive their voices and memories.
🌳 Life
Italian based in the Netherlands who is still struggling with his Dutch.
Among the things I like to do when not at a keyboard or a guitar:
- 🛹 Roll my skate
- 🏄 Chase waves
- 🍺 Enjoy craft beer
- 👪 Raise a new geek
#ActivityPub support in #Madblog
I am glad to announce that Madblog has now officially joined the #Fediverse family.
Madblog has already supported #Webmentions for the past couple of weeks, allowing your blog posts to be mentioned by other sites with Webmentions support (WordPress, Lemmy, HackerNews…) and get those mentions directly rendered on your page.
It now adds ActivityPub support too, using #Pubby, another little Python library that I’ve put together myself (just like Webmentions) as a mean to quickly plug ActivityPub support to any Python Web app.
Webmentions and Pubby follow similar principles and implement a similar API, and you can easily use them to add federation support to your existing Web applications - a single bind_webmentions or bind_activitypub call to your existing Flask/FastAPI/Tornado application should suffice for most of the cases.
Madblog may have now become the easiest way to publish a federated blog - and perhaps the only way that doesn’t require a database, everything is based on plain Markdown files.
If you have a registered domain and a certificate, then hosting your federated blog is now just a matter of:
mkdir -p ~/madblog/markdown
cat <<EOF > ~/madblog/markdown/hello-world.md

This is my first post on [Madblog](https://git.fabiomanganiello.com/madblog)!
EOF

docker run -it \
  -p 8000:8000 \
  -v "$HOME/madblog:/data" \
  quay.io/blacklight/madblog
And Markdown files can be hosted wherever you like - a Git folder, an Obsidian Vault, a Nextcloud Notes installation, a folder on your phone synchronized over SyncThing…
Federation support is also at a quite advanced state compared to e.g. #WriteFreely. It currently supports:
Interactions rendered on the articles: if you like, boost, quote or reply to an article, all interactions are rendered directly at the bottom of the article (interactions with WriteFreely through federated accounts were kind of lost in the void instead)
Guestbook support (optional): mentions to the federated Madblog handle that are not in response to articles are now rendered on a separate
/guestbookrouteEmail notifications: all interactions can have email notifications
Support for quotes, also on Mastodon
Support for mentions, just drop a
@joe@example.comin your Markdown file and Joe will get a notificationSupport for hashtag federation
Support for split-domain configurations, you can host your blog on
blog.example.combut have a Fediverse handle like@blog@example.com. Search by direct post URL on Mastodon will work with both casesSupport for custom profile fields, all rendered on Mastodon, with verification support
Support for moderation, either through blocklist or allowlist, with support for rules on handles/usernames, URLs, domains or regular expressions
A partial (but comprehensive for the provided features) implementation of the Mastodon API
If you want you can follow both the profiles of my blogs - they are now both federated:
My personal blog: @fabio (it used to run WriteFreely before, so if you followed it you may need to unfollow it and re-follow it)
The #Platypush blog: @blog
https://blog.fabiomanganiello.com/article/Madblog-federated-blogging-from-markdown
I have been a quite strong advocate of Webmentions for a long time.
The idea is simple and powerful, and very consistent with the decentralized POSSE approach to content syndication.
Suppose that Alice finds an interesting article on Bob's website, at https://bob.com/article.
She writes a comment about it on her own website, at https://alice.com/comment.
If both Alice's and Bob's websites support Webmentions, then their websites will both advertise an e.g. POST /webmentions endpoint.
When Alice publishes her comment, her website will send a Webmention to Bob's website, with the source URL (https://alice.com/comment) and the target URL (https://bob.com/article).
Bob's website will receive the Webmention, verify that the source URL actually mentions the target URL, and then display the comment on the article page.
No 3rd-party commenting system. No intermediate services. No social media login buttons. No ad-hoc comment storage and moderation solutions. Just a simple, decentralized, peer-to-peer mechanism based on existing Web standards.
This is an alternative (and complementary) approach to federation mechanisms like ActivityPub, which are very powerful but also quite complex to implement, as implementations must deal with concepts such as actors, relays, followers, inboxes, outboxes, and so on.
It is purely peer-to-peer, based on existing Web infrastructure, and with no intermediate actors or services.
Moreover, thanks to Microformats, Webmentions can be used to share any kind of content, not just comments: likes, reactions, RSVPs, media, locations, events, and so on.
However, while the concept is simple, implementing Webmentions support from scratch can be a bit cumbersome, especially if you want to do it right and support all the semantic elements.
I have thus proceeded to implement a simple Python library (but more bindings are on the backlog) that can be easily integrated into any website, and that takes care of all the details of the Webmentions protocol implementation. You only have to worry about writing good semantic HTML, and rendering Webmention objects in your pages.
Quick start
If you use FastAPI or Flask, serve your website as static files and you're ok to use an SQLAlchemy engine to store Webmentions, you can get started in a few lines of code.
pip install "webmentions[db,file,fastapi]"
# For Flask bindings
pip install "webmentions[db,file,flask]"
Base implementation:
import os

from webmentions import WebmentionsHandler
from webmentions.storage.adapters.db import init_db_storage
from webmentions.server.adapters.fastapi import bind_webmentions
from webmentions.storage.adapters.file import FileSystemMonitor

# This should match the public URL of your website
base_url = "https://example.com"

# The directory that serves your static articles/posts.
# HTML, Markdown and plain text are supported
static_dir = "/srv/html/articles"

# A function that takes a path to a created/modified/deleted text/* file
# and maps it to a URL on the Web server to be used as the Webmention source
def path_to_url(path: str) -> str:
    # Convert path (absolute) to a path relative to static_dir
    # and drop the extension.
    # For example, /srv/http/articles/2022/01/01/article.md
    # becomes /2022/01/01/article
    path = os.path.relpath(path, static_dir).rsplit(".", 1)[0].lstrip("/")
    # Convert the path to a URL on the Web server
    # For example, /2022/01/01/article
    # becomes https://example.com/articles/2022/01/01/article
    return f"{base_url.rstrip('/')}/articles/{path}"

##### For FastAPI

from fastapi import FastAPI
from webmentions.server.adapters.fastapi import bind_webmentions

app = FastAPI()

##### For Flask

from flask import Flask
from webmentions.server.adapters.flask import bind_webmentions

app = Flask(__name__)

# ...Initialize your Web app as usual...

# Create a Webmention handler

handler = WebmentionsHandler(
    storage=init_db_storage(engine="sqlite:////tmp/webmentions.db"),
    base_url=base_url,
)

# Bind Webmentions to your app
bind_webmentions(app, handler)

# Create and start the filesystem monitor before running your app
with FileSystemMonitor(
    root_dir=static_dir,
    handler=handler,
    file_to_url_mapper=path_to_url,
) as monitor:
    app.run(...)
This will:
- Register a
POST /webmentionsendpoint to receive Webmentions - Advertise the Webmentions endpoint in every
text/*response provided by the server - Expose a
GET /webmentionsendpoint to list Webmentions (takesresourceURL anddirection(inorout) query parameters) - Store Webmentions in a database (using SQLAlchemy)
- Monitor
static_dirfor changes to HTML or text files, automatically parse them to extract Webmention targets and sources, and send Webmentions when new targets are found
Generic Web framework setup
If you don't use FastAPI or Flask, or you want a higher degree of customization, you can still use the library by implementing and advertising your own Webmentions endpoint, which in turn will simply call WebmentionsHandler.process_incoming_webmention.
You will also have advertise the Webmentions endpoint in your responses, either through:
- A
Linkheader (with a value in the format<https://example.com/webmentions>; rel="webmention") - A
<link>or<a>element in the HTML head or body (in the format<link rel="webmention" href="https://example.com/webmentions">)
An example is provided in the documentation.
Generic storage setup
If you don't want to use SQLAlchemy, you can implement your own storage by implementing the WebmentionsStorage interface (namely the store_webmention, retrieve_webmentions, and delete_webmention methods), then pass that to the WebmentionsHandler constructor.
An example is provided in the documentation.
Manual handling of outgoing Webmentions
The FileSystemMonitor approach is quite convenient if you serve your website (or a least the mentionable parts of it) as static files.
However, if you have a more dynamic website (with posts and comments stored on e.g. a database), or you want to have more control over when Webmentions are sent, you can also call the WebmentionsHandler.process_outgoing_webmentions method whenever a post or comment is published, updated or deleted, to trigger the sending of Webmentions to the referenced targets.
An example is provided in the documentation.
Subscribe to mention events
You may want to add your custom callbacks when a Webmention is sent or received - for example to send notifications to your users when some of their content is mentioned, or to keep track of the number of mentions sent by your pages, or to perform any automated moderation or filtering when mentions are processed etc.
This can be easily achieved by providing custom callback functions (on_mention_processed and on_mention_deleted) to the WebmentionsHandler constructor, and both take a single Webmention object as a parameter.
An example is provided in the documentation.
Filtering and moderation
This library is intentionally agnostic about filtering and moderation, but it provides you with the means to implement your own filtering and moderation logic through the on_mention_processed and on_mention_deleted callbacks.
By default all received Webmentions are stored with WebmentionStatus.CONFIRMED status.
This can be changed by setting the initial_mention_status parameter of the WebmentionsHandler constructor to WebmentionStatus.PENDING, which will cause all received Webmentions to be stored but not visible on the website until they are manually confirmed by an administrator.
You can then use the on_mention_processed callback to implement your own logic to either notify the administrator of new pending mentions, or to automatically confirm them based on some criteria.
A minimal example is provided in the documentation.
Make your pages mentionable
Without good semantic HTML, Webmentions will be quite minimal. They will still work, but they will probably be rendered simply as a source URL and a creation timestamp.
The Webmention specification is intentionally simple, in that the POST endpoint only expects a source URL and a target URL. The rest of the information about the mention (the author, the content, the type of mention, any attachments, and so on) is all derived from the source URL, by parsing the HTML of the source page and extracting the relevant Microformats.
While the Microformats2 specification is quite flexible and a work-in-progress, there are a few basic elements whose usage is recommended to make the most out of Webmentions.
A complete example with a semantic-aware HTML article is provided in the documentation.
Rendering mentions on your pages
Finally, the last step is to render the received Webmentions on your pages.
A
WebmentionsHandler.render_webmentions
helper is provided to automatically generate a safe pre-rendered and reasonably
styled (but customizable through CSS variables) Markup object, which you can
then render in your templates. Example:
from fastapi import FastAPI
from fastapi.templating import Jinja2Templates
from webmentions import WebmentionsHandler
from webmentions.server.adapters.fastapi import bind_webmentions

base_url = "https://example.com"
app = FastAPI()
handler = WebmentionsHandler(...)
bind_webmentions(app, handler)

# ...

@app.get("/articles/{article_id}")
def article(request, article_id: int):
    templates = Jinja2Templates(directory="templates")
    mentions = handler.retrieve_webmentions(
      f"{base_url}/articles/{article_id}",
      WebmentionDirection.IN,
    )

    rendered_mentions = handler.render_webmentions(mentions)
    return templates.TemplateResponse(
      "article.html",
      {
        "request": request,
        "article_id": article_id,
        "mentions": rendered_mentions,
      },
    )
Where article.html is a Jinja template that looks like this:
<!doctype html>
<html>
  <head>
    <title>Example article</title>
  </head>
  <body>
    <main>
      <article class="h-entry">
        <h1 class="p-name">Example article</h1>
        <time class="dt-published" datetime="2026-02-07T21:03:00+01:00">
          Feb 7, 2026
        </time>
        <div class="e-content">
          <p>Your article content goes here.</p>
        </div>
      </article>

      {{ mentions }}
    </div>
  </body>
</html>
More details are provided in the documentation.
For more customizing rendering, a reference Jinja template is also provided in the documentation.
Current implementations
So far the library is used in madblog, a minimal zero-database Markdown-based blogging engine I maintain, which powers both my personal blog and the Platypush blog.
You can see some Webmentions in action on some of my blog posts.
And, if you include a link to any article of mine in your website, and your website supports Webmentions (for example there is a Wordpress plugin), you should see the mention appear in the comments of the article page.
Links
Git automation, either in the form of Gitlab pipelines or Github actions, is amazing. It enables you to automate a lot of software maintenance tasks (testing, monitoring, mirroring repositories, generating documentation, building and distributing packages etc.) that until a couple of years ago used to take a lot of development time. These forms of automation have democratized CI/CD, bringing to the open-source world benefits that until recently either belonged mostly to the enterprise world (such as TeamCity) or had a steep curve in terms of configuration (such as Jenkins).
I have been using Github actions myself for a long time on the Platypush codebase, with a Travis-CI integration to run integration tests online and a ReadTheDocs integration to automatically generate online documentation.
You and whose code?
However, a few things have changed lately, and I don't feel like I should rely much on the tools mentioned above for my CI/CD pipelines.
Github has
too often taken the wrong side
in DMCA disputes since it's been acquired by Microsoft. The
CEO of Github has in the meantime tried to redeem himself,
but the damage in the eyes of many developers, myself included, was done, despite the friendly olive branch
to the community handed over IRC. Most of all, that doesn't change the fact that Github has
taken down more than 2000 other repos in 2020 alone,
often without any appeal or legal support - the CEO bowed down in the case of youtube-dl only because of the massive
publicity that the takedown attracted. Moreover, Github has yet to overcome its biggest contradiction:
it advertises itself like the home for open-source software, but its own source code is not open-source, so you can't
spin up your own instance on your own server. There's also increasing evidence in support of my initial suspicion that
the Github acquisition was nothing but another
old-school Microsoft triple-E operation. Nowadays, when
you want to clone a Github repo you won't be prompted anymore with the HTTPS/SSH link by default. You'll be prompted
with the Github CLI command, which extends the standard git command, but it introduces a couple of naming
inconsistencies here and there. They could have contributed to improving the git tool for everyone's benefit instead
of providing their new tool as the new default, but they have opted not to do so. I'm old enough to have seen quite a
few of these examples in the past, and it never ended well for the extended party. As a consequence of these actions,
I have moved the Platypush repos to a self-hosted Gitlab instance - which comes
with much more freedom, but also no more Github actions.
And, after the announcement of the planned migration from travis-ci.org to travis-ci.com, with greater focus on enterprise, a limited credit system for open-source projects and a migration process that is largely manual, I have also realized that Travis-CI is another service that can't be relied upon anymore when it comes to open-source software. And, again, Travis-CI is plagued by the same contradiction as Github - it claims to be open-source friendly, but it's not open-source itself, and you can't install it on your own machine.
ReadTheDocs, luckily, seems to be still coherent with its mission of supporting open-source developers, but I'm also keeping an eye on them just in case :)
Building a self-hosted CI/CD pipeline
Even though abandoning closed-source and unreliable cloud development tools is probably the right thing to do, that leaves a hole behind: how do we bring the simplicity of the automation provided by those tools to our new home - and, preferably, in such a format that it can be hosted and moved anywhere?
Github and Travis-CI provide a very easy way of setting up CI/CD pipelines. You read the documentation, upload a YAML file to your repo, and all the magic happens. I wanted to build something that was that easy to configure, but that could run anywhere, not only in someone else's cloud.
Building a self-hosted pipeline, however, also brings its advantages. Besides liberating yourself of the concern of handing your hard-worked code to someone else who can either change their mind about their mission, or take it down overnight, you have the freedom of setting up the environment for build and test however you please and customize it however you please. And you can easily set up integrations such as automated notifications over whichever channel you like, without the headache of installing and configuring all the dependencies to run on someone else's cloud.
In this article we'll how to use Platypush to set up a pipeline that:
-
Reacts to push and tag events on a Gitlab or Github repository and runs custom Platypush actions in YAML format or Python code.
-
Automatically mirrors the new commits and tags to another repo - in my case, from Gitlab to Github.
-
Runs a suite of tests.
-
If the tests succeed, it proceeds with packaging the new version of the codebase - in my case, I run the automation to automatically create the new
platypush-gitpackage for Arch Linux on new pushes, and the newplatypushArch package as well as thepippackage on new tags. -
If the tests fail, it sends a notification (over email, Telegram, Pushbullet or whichever plugin supported by Platypush). It also sends a notification if the latest run of tests has succeeded and the previous one was failing.
Note: since I have moved my projects to a self-hosted Gitlab server, I could have also relied on the native Gitlab CI/CD pipelines, but I have eventually opted not to do so for two reasons:
-
Setting up the whole Docker+Kubernetes automation required for the CI/CD pipeline proved to be a quite cumbersome process. Additionally, it may require some properly beefed machine in order to run smoothly, while ideally I wanted something that could run even on a RaspberryPi, provided that the building and testing processes aren't too resource-heavy themselves.
-
The alternative provided by Gitlab to setting up your Kubernetes instance and configuring the Gitlab integration is to get a bucket on the cloud to spin a container that runs all you have to run. But if I have gone so far to set up my own self-hosted infrastructure for hosting my code, I certainly don't want to give up on the last mile in exchange of a small discount on the Google Cloud services :)
However, if either you have enough hardware resources and time to set up your own Kubernetes infrastructure to integrate with Gitlab, or you don't mind running your CI/CD logic on the Google cloud, Gitlab CI/CD pipelines are something that you may consider - if you don't have the constraints above then they are very powerful, flexible and easy to set up.
Installing Platypush
Let's start by installing Platypush with the required integrations.
If you want to set up an automation that reacts on Gitlab events then you'll only need the http integration, since
we'll use Gitlab webhooks to trigger the
automation:
$ [sudo] pip install 'platypush[http]'
If you want to set up the automation on a Github repo you'll only have one or two additional dependencies, installed
through the github integration:
$ [sudo] pip install 'platypush[http,github]'
If you want to be notified of the status of your builds then you may want to install the integration required by the communication mean that you want to use. We'll use Pushbullet in this example because it's easy to set up and it natively supports notifications both on mobile and desktop:
$ [sudo] pip install 'platypush[pushbullet]'
Feel free however to pick anything else - for instance, you can refer to this article for a Telegram set up or this article for a mail set up, or take a look at the Twilio integration if you want automated notifications over SMS or Whatsapp.
Once installed, create a ~/.config/platypush/config.yaml file that contains the service configuration - for now we'll
just enable the web server:
backend.http:
  enabled: True
Setting up a Gitlab hook
Gitlab webhooks are a very simple and powerful way of triggering things when something happens on a Gitlab repo. All you have to do is setting up a URL that should be called upon a repository event (push, tag, new issue, merge request etc.), and set up a piece of automation on the endpoint that reacts to the event.
The only requirement for this mechanism to work is that the endpoint must be reachable from the Gitlab host - it means that the host running the Platypush web service must either be publicly accessible, on the same network or VPN as the Gitlab host, or the Platypush web port must be tunneled/proxied to the Gitlab host.
Platypush offers a very easy way to expose custom endpoints through the
WebhookEvent. All you have to do is set up
an event hook that reacts to a WebhookEvent at a specific endpoint. For example, create a new event hook under
~/.config/platypush/scripts/gitlab.py:
from platypush.event.hook import hook
from platypush.message.event.http.hook import WebhookEvent

# Token to be used to authenticate the calls from Gitlab
gitlab_token = 'YOUR_TOKEN_HERE'


@hook(WebhookEvent, hook='repo-push')
def on_repo_push(event, **context):
    # Check that the token provided over the
    # X-Gitlab-Token header is valid
    assert event.headers.get('X-Gitlab-Token') == gitlab_token, \
      'Invalid Gitlab token'

    print('Add your logic here')
This hook will react when an HTTP request is received on http://your-host:8008/hook/repo-push. Note that, unlike
most of the other Platypush endpoints, custom hooks are not authenticated - that's because they may be called from
any context, and you don't necessarily want to share your Platypush instance credentials or token with 3rd-parties.
Instead, it's up to you to implement whichever authentication policy you like over the requests.
After adding your endpoint, start Platypush:
$ platypush
Now, in order to set up a new webhook, navigate to your Gitlab project -> Settings -> Webhooks.

Enter the URL to your webhook and the secret token and select the events you want to react to - in this example, we'll select new push events.
You can now test the endpoint through the Gitlab interface itself. If it all went well, you should see a Received
event line with a content like this on the standard output or log file of Platypush:
{
  "type": "event",
  "target": "platypush-host",
  "origin": "gitlab-host",
  "args": {
    "type": "platypush.message.event.http.hook.WebhookEvent",
    "hook": "repo-push",
    "method": "POST",
    "data": {
      "object_kind": "push",
      "event_name": "push",
      "before": "previous-commit-id",
      "after": "current-commit-id",
      "ref": "refs/heads/master",
      "checkout_sha": "current-commit-id",
      "message": null,
      "user_id": 1,
      "user_name": "Your User",
      "user_username": "youruser",
      "user_email": "you@email.com",
      "user_avatar": "path to your avatar",
      "project_id": 1,
      "project": {
        "id": 1,
        "name": "My project",
        "description": "Project description",
        "web_url": "https://git.platypush.tech/platypush/platypush",
        "avatar_url": "https://git.platypush.tech/uploads/-/system/project/avatar/3/icon-256.png",
        "git_ssh_url": "git@git.platypush.tech:platypush/platypush.git",
        "git_http_url": "https://git.platypush.tech/platypush/platypush.git",
        "namespace": "My project",
        "visibility_level": 20,
        "path_with_namespace": "platypush/platypush",
        "default_branch": "master",
        "ci_config_path": null,
        "homepage": "https://git.platypush.tech/platypush/platypush",
        "url": "git@git.platypush.tech:platypush/platypush.git",
        "ssh_url": "git@git.platypush.tech:platypush/platypush.git",
        "http_url": "https://git.platypush.tech/platypush/platypush.git"
      },
      "commits": [
        {
          "id": "current-commit-id",
          "message": "This is a commit",
          "title": "This is a commit",
          "timestamp": "2021-03-06T20:02:25+01:00",
          "url": "https://git.platypush.tech/platypush/platypush/-/commit/current-commit-id",
          "author": {
            "name": "Your Name",
            "email": "you@email.com"
          },
          "added": [],
          "modified": [
            "tests/my_test.py"
          ],
          "removed": []
        }
      ],
      "total_commits_count": 1,
      "push_options": {},
      "repository": {
        "name": "My project",
        "url": "git@git.platypush.tech:platypush/platypush.git",
        "description": "Project description",
        "homepage": "https://git.platypush.tech/platypush/platypush",
        "git_http_url": "https://git.platypush.tech/platypush/platypush.git",
        "git_ssh_url": "git@git.platypush.tech:platypush/platypush.git",
        "visibility_level": 20
      }
    },
    "args": {},
    "headers": {
      "Content-Type": "application/json",
      "User-Agent": "GitLab/version",
      "X-Gitlab-Event": "Push Hook",
      "X-Gitlab-Token": "YOUR GITLAB TOKEN",
      "Connection": "close",
      "Host": "platypush-host:8008",
      "Content-Length": "lenght"
    }
  }
}
These are all fields provided on the event object that you can use in your hook to build your custom logic.
Setting up a Github integration
If you want to keep using Github but run the CI/CD pipelines on another host with no dependencies on the Github actions, you can leverage the Github backend to monitor your repos and fire Github events that you can build your hooks on when something happens.
First, head to your Github profile to create a new
API access token. Then
add the configuration to ~/.config/platypush/config.yaml under the backend.github section:
backend.github:
  user: your_user
  user_token: your_token
  # Optional list of repos to monitor (default: all user repos)
  repos:
    - https://github.com/you/myrepo1.git
    - https://github.com/you/myrepo2.git

  # How often the backend should poll for updates (default: 60 seconds)
  poll_seconds: 60

  # Maximum events that will be triggered if a high number of events has
  # been triggered since the last poll (default: 10)
  max_events_per_scan: 10
Start the service, and on e.g. the first repository push event you should see a Received event log line like this:
{
  "type": "event",
  "target": "your-host",
  "origin": "your-host",
  "args": {
    "type": "platypush.message.event.github.GithubPushEvent",
    "actor": {
      "id": 1234,
      "login": "you",
      "display_login": "You",
      "url": "https://api.github.com/users/you",
      "avatar_url": "https://avatars.githubusercontent.com/u/1234?"
    },
    "event_type": "PushEvent",
    "repo": {
      "id": 12345,
      "name": "you/myrepo1",
      "url": "https://api.github.com/repos/you/myrepo1"
    },
    "created_at": "2021-03-03T18:20:27+00:00",
    "payload": {
      "push_id": 123456,
      "size": 1,
      "distinct_size": 1,
      "ref": "refs/heads/master",
      "head": "current-commit-id",
      "before": "previous-commit-id",
      "commits": [
        {
          "sha": "current-commit-id",
          "author": {
            "email": "you@email.com",
            "name": "You"
          },
          "message": "This is a commit",
          "distinct": true,
          "url": "https://api.github.com/repos/you/myrepo1/commits/current-commit-id"
        }
      ]
    }
  }
}
You can easily create an event hook that reacts to such events to run your automation - e.g. under
~/.config/platypush/scripts/github.py:
from platypush.event.hook import hook
from platypush.message.event.github import GithubPushEvent


@hook(GithubPushEvent)
def on_repo_push(event, **context):
  # Run this action only for a specific repo
  if event.repo['name'] != 'you/myrepo1':
    return

  print('Add your logic here')
And here you go - you should now be ready to create your automation routines on Github events.
Automated repository mirroring
Even though I have moved the Platypush repos to a self-hosted domain, I still keep a mirror of them on Github. That's because lots of people have already cloned the repos over the years and may lose updates if they haven't seen the announcement about the transfer. Also, registering to a new domain is often a barrier for users who want to create issues. So, even though I and Github are no longer friends, I still need a way to easily mirror each new commit on my domain to Github - but you might as well have another compelling case for backing up/mirroring your repos. The way I'm currently achieving this is by cloning the main instance of the repo on the machine that runs the Platypush service:
$ git clone git@git.you.com:you/myrepo.git /opt/repo
Then add a new remote that points to your mirror repo:
$ cd /opt/repo
$ git remote add mirror git@github.com:/you/myrepo.git
$ git fetch
Then try a first git push --mirror to make sure that the repos are aligned and all conflicts are solved:
$ git push --mirror -v mirror
Then add a new sync_to_mirror function in your Platypush script file that looks like this:
import logging
import os
import subprocess

repo_path = '/opt/repo'

# ...

def sync_to_mirror():
    logging.info('Synchronizing commits to mirror')
    os.chdir(repo_path)
    # Pull the updates from the main repo
    subprocess.run(['git', 'pull', '--rebase', 'origin', 'master'])
    # Sync the updates to the repo
    subprocess.run(['git', 'push', '--mirror', '-v', 'mirror'])
    logging.info('Synchronizing commits to mirror: DONE')
And just call it from the previously defined on_repo_push hook, either the Gitlab or Github variant:
# ...
def on_repo_push(event, **_):
    # ...
    sync_to_mirror()
    # ...
Now on each push the repository clone stored under /opt/repo will be updated and any new commits and tags will be
mirrored to the mirror repository.
Running tests
If our project is properly set up, then it probably has a suite of unit/integration tests that is supposed to be run on
each change to verify that nothing is broken. It's quite easy to configure the previously created hook so that it runs
the tests on each push. For instance, if your tests are stored under the tests folder of your project and you use
pytest:
import datetime
import os
import pathlib
import shutil
import subprocess

from platypush.event.hook import hook
from platypush.message.event.http.hook import WebhookEvent

# Path where the latest version of the repo will be cloned
tmp_path = '/tmp/repo'
# Path where the results of the tests will be stored
logs_path = '/var/log/tests'

# ...

def run_tests():
  # Clone the repo in /tmp
  shutil.rmtree(tmp_path, ignore_errors=True)
  subprocess.run(['git', 'clone', 'git@git.you.com:you/myrepo.git', tmp_path])
  os.chdir(os.path.join(tmp_path, 'tests'))
  passed = False

  try:
    # Run the tests
    tests = subprocess.Popen(['pytest'],
                             stdout=subprocess.PIPE,
                             stderr=subprocess.PIPE)

    stdout = tests.communicate()[0].decode()
    passed = tests.returncode == 0

    # Write the stdout to a logfile
    pathlib.Path(logs_path).mkdir(parents=True, exist_ok=True)
    logfile = os.path.join(logs_path,
                           f'{datetime.datetime.now().isoformat()}_'
                           f'{"PASSED" if passed else "FAILED"}.log')

    with open(logfile, 'w') as f:
      f.write(stdout)
  finally:
    shutil.rmtree(tmp_path, ignore_errors=True)

  # Return True if the tests passed, False otherwise
  return passed

# ...

@hook(WebhookEvent, hook='repo-push')
# or
# @hook(GithubPushEvent)
def on_repo_push(event, **_):
  # ...
  passed = run_tests()
  # ...
Upon push event, the latest version of the repo will be cloned under /tmp/repo and the suite of tests will be run.
The output of each session will be stored under /var/log/tests in a file formatted like
<ISO_timestamp>_<PASSED|FAILED>.log. To make things even more robust, you can create a new virtual environment under
the temporary directory, install your repo with all of its dependency in the new virtual environment and run the tests
from there, or spin a Docker instance with the required configuration, to make sure that the tests would also pass on a
fresh installation and prevent the "but it works on my box" issue.
Serve the test results over HTTP
Now you can simply serve /var/log/tests over an HTTP server and the logs can be accessed from your browser. Simple
case:
$ cd /var/log/tests
$ python -m http.server 8000
The logs will be served on http://host:8000. You can also serve the directory through a proper web server like Nginx
or Apache.

It doesn't come with all the bells and whistles of the Jenkins or Travis-CI UI, but it's simple and good enough for its job - and it's not hard to extend it with a fancier UI if you like.
Another nice addition is to download some of those nice passed/failed badge images that you find on many Github
repositories to your Platypush box. When a test run completes, just edit your hook to copy the associated banner image
(e.g. passed.svg or failed.svg) to e.g. /var/log/tests/status.svg:
import os
import shutil

# ...

def run_tests():
    # ...
    passed = tests.returncode == 0
    badge_path = '/path/to/passed.svg' if passed else '/path/to/failed.svg'
    shutil.copy(badge_path, os.path.join(logs_path, 'status.svg'))
    # ...
Then embed the status in your README.md:
[](http://your-host:8000)
And there you go - you can now show off a dynamically generated and self-hosted status badge on your README without relying on any cloud runner.
Automatic build and test notifications
Another useful feature of most of the popular cloud services is the ability to send notifications when a build status changes. This is quite easy to set up with Platypush, as the application provides several plugins for messaging. Let's look at an example where a change in the status of our tests triggers a notification to our Pushbullet account, which can be delivered both to our desktop and mobile devices. Download the Pushbullet app if you want the notifications to be delivered to your mobile, get an API token and then install the dependencies for the Pushbullet integration for Platypush:
$ [sudo] pip install 'platypush[pushbullet]'
Then configure the Pushbullet plugin and backend in ~/.config/platypush/config.yaml:
backend.pushbullet:
    token: YOUR_PUSHBULLET_TOKEN
    device: platypush

pushbullet:
    enabled: True
Now simply modify your push hook to send a notification when the status of build changes. We will also use the
variable plugin to retrieve and store the
latest status, so that notifications are triggered only when the status changes:
from platypush.context import get_plugin
from platypush.event.hook import hook
from platypush.message.event.http.hook import WebhookEvent

# Name of the variable that holds the latest run status
last_tests_passed_var = 'LAST_TESTS_PASSED'

# ...

def run_tests():
  # ...
  passed = tests.returncode == 0
  # ...
  return passed

# ...

@hook(WebhookEvent, hook='repo-push')
# or
# @hook(GithubPushEvent)
def on_repo_push(event, **_):
  variable = get_plugin('variable')
  pushbullet = get_plugin('pushbullet')

  # Get the status of the last run
  response = variable.get(last_tests_passed_var).output
  last_tests_passed = int(response.get(last_tests_passed_var, 0))

  # ...

  passed = run_tests()
  if passed and not last_tests_passed:
    pushbullet.send_note(body='The tests are now PASSING',
                         # If device is not set then the notification will
                         # be sent to all the devices connected to the account
                         device='my-mobile-name')
  elif not passed and last_tests_passed:
    pushbullet.send_note(body='The tests are now FAILING',
                         device='my-mobile-name')

  # Update the last_test_passed variable
  variable.set(**{last_tests_passed_var: int(passed)})

  # ...
The nice addition of this approach is that any other Platypush device with the Pushbullet backend enabled and connected
to the same account will receive a
PushbulletEvent
when a Pushbullet note is sent, and you can easily leverage this to build some downstream logic with hooks that react to
these events.
Continuous delivery
Once we have a logic in place that automatically mirrors and tests our code and notifies us about status changes, we can take things a step further and set up our pipeline to also build a package for our applications if the tests are successful.
Let's consider in this article the example of a Python application whose new releases are tagged through git tags,
and each time a new version is released we want to create a pip package and upload it to the online PyPI registry.
However, you can easily adapt this example to work with any build and release process.
Twine is a quite popular option when it comes to uploading
packages to the PyPI registry. Let's install it:
$ [sudo] pip install twine
Then create a Gitlab webhook that reacts to tag events, or react to a
GithubCreateEvent
if you are using Github, and create a Platypush hook that reacts to tag events by running the logic of on_repo_push,
and additionally make a package build and upload it with Twine if the tests are successful:
import importlib
import os
import subprocess

from platypush.event.hook import hook
from platypush.message.event.http.hook import WebhookEvent

# Path where the latest version of the repo has been cloned
tmp_path = '/tmp/repo'

# Initialize these variables with your PyPI credentials
os.environ['TWINE_USERNAME'] = 'your-pypi-user'
os.environ['TWINE_PASSWORD'] = 'your-pypi-pass'

# ...

def upload_pip_package():
  os.chdir(tmp_path)
  # Build the package
  subprocess.run(['python', 'setup.py', 'sdist', 'bdist_wheel'])

  # Check the version of your app - for example from the
  # yourapp/__init__.py __version__ field
  app = importlib.import_module('yourapp')
  version = app.__version__

  # Check that the archive file has been created
  archive_file = os.path.join('.', 'dist', f'yourapp-{version}.tar.gz')
  assert os.path.isfile(archive_file), \
    f'The target file {archive_file} was not created'

  # Upload the archive file to PyPI
  subprocess.run(['twine', 'upload', archive_file])

@hook(WebhookEvent, hook='repo-tag')
# or
# @hook(GithubCreateEvent)
def on_repo_tag(event, **_):
  # ...

  passed = run_tests()
  if passed:
    upload_pip_package()

  # ...
And here you go - you now have an automated way of building and releasing your application!
Continuous delivery of web applications
We have seen in this article some examples of CI/CD for stand-alone applications with a complete test+build+release
pipeline. The same concept also applies to web services and applications. If your repository stores the source code of a
website, then you can easily create pieces of automation that react to push events and pull the changes on the web
server and restart the web service if required. This is in fact the way I'm currently managing updates on the
Platypush blog and homepage. Let's see a small example where
we have a Platypush instance running on the same machine as the web server, and suppose that our website is served
under /srv/http/myapp (and, of course, that the user that runs the Platypush service has write permissions on this
location). It's quite easy to tweak the previous hook example so that it reacts to push events on this repo by pulling
the latest changes, runs e.g. npm run build to build the new dist files and then copies the dist folder to our web
server directory:
import os
import shutil
import subprocess

from platypush.event.hook import hook
from platypush.message.event.http.hook import WebhookEvent

# Path where the latest version of the repo has been cloned
tmp_path = '/tmp/repo'

# Path of the web application
webapp_path = '/srv/http/myapp'

# Backup path of the web application
backup_webapp_path = '/srv/http/myapp-backup'

# ...

def update_webapp():
  os.chdir(tmp_path)
  # Build the app
  subprocess.run(['npm', 'install'])
  subprocess.run(['npm', 'run', 'build'])

  # Verify that the dist folder has been created
  dist_path = os.path.join('.', 'dist')
  assert os.path.isdir(dist_path), 'dist path not created'

  # Remove the previous app backup folder if present
  shutil.rmtree(backup_webapp_path, ignore_errors=True)
  # Backup the old web app folder
  shutil.move(webapp_path, backup_webapp_path)
  # Move the dist folder to the web app folder
  shutil.move(dist_path, webapp_path)

@hook(WebhookEvent, hook='repo-push')
# or
# @hook(GithubPushEvent)
def on_repo_tag(event, **_):
  # ...

  passed = run_tests()
  if passed:
    update_webapp()

  # ...